Testing the contract of an image means running it as a user would and asking it questions without ever modifying it: does it start, does it answer, does it accept its configuration, does it run without privilege, does it stop on docker stop, does it tell the truth about its state? This lesson writes a test script, tester-contrat.sh, that returns code 0 for a compliant image and code 1, with a message that names the check, for an unusable image.
A build that succeeds does not prove the image can be used. You will run the same script against a correct image, then against six deliberately broken images, and read each rejection. All the measurements come from Docker Engine 29.9.2 and Buildx 0.38.1, on a Debian 13 VM, with the python:3.15.2-slim base image.
Several names in this lesson are French because the commands and outputs are the ones that were run: releve-contrat ("contract report") is the example service and its image, CANAL ("channel") and CADENCE ("rate") are its variables, /pret ("ready") and /travail ("work") its routes, essai ("trial") and defaut ("default") the values given to CANAL, and demarrage, fonctionnement, sante and arret ("startup", "operation", "health", "shutdown") are check names. The same goes for file names, shell functions and image tags such as 1.0-sante-processus. They are identifiers, so they stay as they are. The messages that the script and the program write after those names are in English.
The lesson starts from the check script of Separate build from runtime: the multi-stage build (set -e, an assignment then a test) and generalizes it into a protocol. You have already seen, in Startup, readiness and health, the three health states, the settings of a probe and the role of depends_on on the Compose side. Here, the probe is declared by the image itself, and it is the test script that judges it.
What you will learn
- List what a user of the image can expect, that is, its contract
- Write a test script that bounds every wait instead of sleeping for a fixed time
- Declare a
HEALTHCHECKin the image and read.Config.Healthcheckand.State.Health - Check the configuration, the uid, the
--read-onlymode and shutdown on SIGTERM - Have the same script reject six broken images
- Write the durations of a
HEALTHCHECKin a unit that hadolint accepts
Prerequisites
- Having read Build an image for several architectures and Separate build from runtime: the multi-stage build, including the section on
verifier-image.sh - Having read Startup, readiness and health, which explains the three health states, the settings of a probe and
depends_on - Knowing what
USERchanges (Docker USER: run an image as non-root without breaking it) and why a stop can take ten seconds (Container lifecycle, PID 1 and clean shutdown in Docker) - A working Docker 29.9.2 (Docker installation),
bash,curl,awkandtimeout, in their GNU Linux version: the script usesdate +%s.%Nandtimeout, which do not work as they are on macOS
What is the contract of an image?
The contract of an image is the list of what a person who uses it can expect without reading its Dockerfile. They do not need to know how the image is built: they run docker run, then docker stop, and assume everything goes well. Each expectation becomes a check that the script runs from the outside.
| User expectation | Script check | What the script observes |
|---|---|---|
| The image starts | demarrage | the /pret route answers before a 15 s limit |
| It does its work | fonctionnement | /pret and /travail return the expected answer |
| It is configurable | configuration | without the required variable, it stops with a non-zero code and a message; an optional variable is taken into account |
| It needs no privilege | permissions | uid other than 0; service that runs under --read-only |
| It stops when asked | arret | exit code 0 or 143, in under 8 s |
| It reports its state | sante | a HEALTHCHECK exists and follows the real work |
The names in the middle column serve as labels: each message of the script starts with one of them, in square brackets, so that the rejection says at once what it is about.
An external test avoids a trap that the tests of the code do not see. The unit test of the application passes even if the image forgets a file, runs as root or ignores SIGTERM. Only running the final image exposes these defects, as the section on verifier-image.sh showed for the loader, the time zones and the certificates. Specialized tools exist to describe the structure of an image, such as Container Structure Test (in French); here, the script stays shell so that each check is readable.
Which service does the demonstration use?
The releve-contrat service is a small Python program that plays the role of the application to ship. It listens on port 8080, answers on two routes and knows how to stop cleanly. Create a working directory, then the releve.py file.
import os, sys, time, signal, threadingfrom http.server import ThreadingHTTPServer, BaseHTTPRequestHandler
canal = os.environ.get("CANAL")if not canal:    print("error: the CANAL variable is required", file=sys.stderr)    sys.exit(78)cadence = float(os.environ.get("CADENCE", "1"))data = os.environ.get("DATA_DIR", "/data")source = os.path.join(data, "source")journal = os.environ.get("JOURNAL")if journal:    with open(journal, "a") as f:        f.write("demarrage\n")open(source, "a").close()etat = {"dernier": 0.0}arret = threading.Event()
def travailler():    while not arret.is_set():        if os.path.exists(source):            with open(os.path.join(data, "dernier"), "w") as f:                f.write(str(time.time()))            etat["dernier"] = time.time()        arret.wait(cadence)
class H(BaseHTTPRequestHandler):    def reponse(self, code, texte):        corps = (texte + "\n").encode()        self.send_response(code)        self.send_header("Content-Length", str(len(corps)))        self.end_headers()        self.wfile.write(corps)    def do_GET(self):        if self.path == "/pret":            self.reponse(200, f"pret canal={canal} cadence={cadence:g}")        elif self.path == "/travail":            age = time.time() - etat["dernier"]            if age <= 5 * cadence:                self.reponse(200, f"travail ok age={age:.1f}")            else:                self.reponse(503, "work too old or source missing")        else:            self.reponse(404, "unknown")    def log_message(self, *a):        pass
srv = ThreadingHTTPServer(("0.0.0.0", 8080), H)def sigterm(signum, frame):    arret.set()    threading.Thread(target=srv.shutdown).start()signal.signal(signal.SIGTERM, sigterm)threading.Thread(target=travailler, daemon=True).start()print("service ready", flush=True)srv.serve_forever()print("clean shutdown", flush=True)sys.exit(0)
The program boils down to three behaviors, each of which is something to test.
- It refuses to start without the
CANALvariable: a message on the error output, exit code 78 (the value that thesysexitsconvention reserves for configuration errors). TheCADENCEvariable, on the other hand, is optional. - It works continuously: a loop rewrites the
/data/dernierfile as long as the/data/sourcefile exists./pretanswers 200 as soon as the server listens./travailanswers 200 if the work is less than five rates old, and 503 otherwise, that is, when/data/sourcehas disappeared. - It handles SIGTERM: the handler stops the server, the program prints
clean shutdownand exits with code 0.
One last variable, JOURNAL, is optional: if it is set, the program writes a line there at startup. The correct image does not set it; one of the broken images uses it.
The difference between /pret and /travail is the heart of the lesson: /pret says that the process answers, /travail says that it does what it exists for.
How does the image declare its health?
An image declares its health with the HEALTHCHECK instruction of the Dockerfile: whoever runs the image, with docker run or in Compose, gets the probe without writing anything. The states and the settings are those of the lesson on the health of Compose services: starting as long as no probe has succeeded, healthy after a successful probe, unhealthy after retries failures in a row. Only the place where you declare them changes. The --start-interval option, available since Docker Engine 25.0 according to the Dockerfile documentation, sets how often probes run during the grace period. Here is the Dockerfile of the correct image.
FROM python:3.15.2-slim@sha256:8c13a3f37a6a5b71498228e902c4b9f51c1f7900d49fabf71f9a650c6120e0d0ENV PYTHONUNBUFFERED=1WORKDIR /appCOPY releve.py /app/releve.pyRUN mkdir /data && chown 10001:10001 /dataEXPOSE 8080USER 10001HEALTHCHECK --interval=2s --timeout=1s --start-period=3s --start-interval=0.5s --retries=2 CMD ["python", "-c", "import urllib.request; urllib.request.urlopen(\"http://127.0.0.1:8080/travail\", timeout=1)"]CMD ["python", "/app/releve.py"]Three choices deserve a close reading. /data belongs to uid 10001 and USER 10001 applies afterwards, so the program runs without privilege and writes where it is allowed to. The exec form of CMD, with square brackets, makes the Python program PID 1 of the container; that is what lets it receive SIGTERM. Finally, the probe calls /travail, not /pret, with Python, already present in the image: a probe must not require a tool that the image does not install.
The probe is written here in exec form, a JSON array after CMD. The shell form, HEALTHCHECK CMD command, is also allowed: Docker then runs it with /bin/sh -c, which assumes a shell in the image, and .Config.Healthcheck.Test shows CMD-SHELL instead of CMD. In an image without a shell, only the exec form works.
Build the image with an explicit version, never latest, then read what Docker recorded.
docker build -t releve-contrat:1.0 .docker inspect --format '{{json .Config.Healthcheck}}' releve-contrat:1.0{"Test":["CMD","python","-c","import urllib.request; urllib.request.urlopen(\"http://127.0.0.1:8080/travail\", timeout=1)"],"Interval":2000000000,"Timeout":1000000000,"StartPeriod":3000000000,"StartInterval":500000000,"Retries":2}Docker stores the durations in nanoseconds: Interval is 2000000000, so 2 s, and StartInterval 500000000, so 0.5 s. The options of the instruction bear the names of the Compose settings, with two hyphens instead of an underscore (--start-period for start_period).
| Option | Value here | Role |
|---|---|---|
--interval | 2 s | delay between two probes |
--timeout | 1 s | maximum duration of a probe |
--retries | 2 | consecutive failures before the unhealthy state |
--start-period | 3 s | grace period at startup |
--start-interval | 0.5 s | delay between two probes during that grace period |
As long as no probe has succeeded, the state is starting. Run the image with a long grace period and a first probe at 10 s, then read the state right away.
docker run -d --name m-st --health-start-period 30s --health-start-interval 10s -e CANAL=x releve-contrat:1.0docker inspect --format '{{json .State.Health}}' m-stdocker ps --filter name=m-st --format '{{.Status}}'sleep 12docker inspect --format '{{json .State.Health.Status}}' m-stdocker rm -f m-st{"Status":"starting","FailingStreak":0,"Log":[]}Up Less than a second (health: starting)"healthy"The two readings differ as follows: right after the launch, no probe has run yet (Log is empty) and the state is starting. Twelve seconds after the launch, the first probe has succeeded and the state is healthy, without waiting for the 30 s of grace period to end: one successful probe during that period is enough.
How do you choose the bounds of the probe?
Four bounds set the probe, and each answers a precise problem. The engine runs a probe, waits for it to finish, then counts the interval from that end before launching another: two probes never overlap. To check this, you build an image whose probe sleeps for 5 seconds, then run it with --health-interval 2s and --health-timeout 10s. Work in a separate directory, so as not to overwrite the Dockerfile of the lesson. The probe script is the following.
#!/bin/shsleep 5exit 0The Dockerfile copies this script into the image and lets it run for 300 seconds, the time of the measurements.
FROM alpine:3.24.3@sha256:be2656061b536c1883c4034790e21d0a09c5aaaf51968b89368a3c0371ea2c9aCOPY sonde.sh /sonde.shRUN chmod +x /sonde.shCMD ["sleep", "300"]Build the image, then run the first case. The health log gives the start and the end of each probe.
docker build -t sonde-lente:1.0 .docker run -d --name hc-long --health-cmd /sonde.sh --health-interval 2s --health-timeout 10s --health-retries 10 --health-start-period 0s sonde-lente:1.0sleep 22docker inspect --format '{{range .State.Health.Log}}{{.Start}} {{.End}} rc={{.ExitCode}} out={{printf "%q" .Output}}{{"\n"}}{{end}}' hc-long2026-11-03 14:41:01.154901397 +0000 UTC 2026-11-03 14:41:06.193151098 +0000 UTC rc=0 out=""2026-11-03 14:41:08.193598519 +0000 UTC 2026-11-03 14:41:13.221457609 +0000 UTC rc=0 out=""2026-11-03 14:41:15.222217271 +0000 UTC 2026-11-03 14:41:20.251444286 +0000 UTC rc=0 out=""Compare each Start with the End of the previous line: 14:41:06.19 then 14:41:08.19, exactly 2 seconds. The next probe therefore waits for the previous one to finish, even if it lasts longer than the interval, and the real rhythm is the duration of the probe plus the interval.
Remove this container, then run again with --health-timeout 3s, still with the 5-second probe. The engine kills the attempt at 3 seconds, and that attempt counts as a failure.
docker rm -f hc-longdocker run -d --name hc-court --health-cmd /sonde.sh --health-interval 2s --health-timeout 3s --health-retries 10 --health-start-period 0s sonde-lente:1.0sleep 20docker inspect --format '{{range .State.Health.Log}}{{.Start}} {{.End}} rc={{.ExitCode}} out={{printf "%q" .Output}}{{"\n"}}{{end}}' hc-courtdocker rm -f hc-court2026-11-03 14:41:23.601239318 +0000 UTC 2026-11-03 14:41:26.647349491 +0000 UTC rc=-1 out="Health check exceeded timeout (3s)"2026-11-03 14:41:28.64799245 +0000 UTC 2026-11-03 14:41:31.675077976 +0000 UTC rc=-1 out="Health check exceeded timeout (3s)"2026-11-03 14:41:33.675922544 +0000 UTC 2026-11-03 14:41:36.706129849 +0000 UTC rc=-1 out="Health check exceeded timeout (3s)"The -1 code and the Health check exceeded timeout (3s) message show what --timeout does: a blocked probe does not last forever, it is interrupted and counts as a failure. The other three bounds read as follows.
--retries: with 2 at the minimum, an isolated failure (a hiccup of the machine) does not declare the service sick.--start-period: a service that is slow to start is not judged too early, the failures of this period do not count, until the first successful probe.--interval: the shorter it is, the faster the state reacts, and the more the probe consumes.
To choose, compute the delay after which the container is declared unhealthy. The Compose lesson gives it as an order of magnitude: interval times retries, plus the duration of each probe. Here is the same formula taken at its worst: after the start period, retries failures are needed, and each failure lasts at most timeout, since the interval is counted after the end of the attempt. That gives retries × (timeout + interval). With the Dockerfile of the lesson (--interval=2s, --timeout=1s, --retries=2), that is 2 × (1 + 2) = 6 seconds, not counting the 3 s of grace period. The --timeout therefore enters this delay: choose it just above the normal duration of the probe.
Two measurements check the formula, and they can be read without being replayed. The first is about the probe alone: the sonde-lente:1.0 image was run with --health-cmd 'sleep 10' --health-interval 2s --health-timeout 1s --health-retries 2 --health-start-period 0s, so that each attempt is interrupted after one second. The state read about every 3 s is starting at 3.27 s and at 6.29 s, then unhealthy at 9.31 s. The log gives the exact moment of the change: the second failure ends 4.06 s after the start of the first attempt, which follows the launch by 2 s, that is, around 6.1 s, very close to the 6 s computed. The reading at 6.29 s still says starting because the container had existed for slightly less than 6.29 s at that moment. Finally, the ends of two consecutive failures are 3.03 s apart, that is, 1 s of timeout plus 2 s of interval.
The formula does not count the service's own delay. Here, /travail only returns 503 when the last write is more than five rates old: between 4 and 5 s after /data/source is cut (4.1 to 4.3 s over four measurements). This delay adds to that of the probe.
The second measurement is about the example of the lesson: after /data/source is cut, the first 503 arrives about 4.2 s after the cut, then the state goes to unhealthy after a further 2.5 to 4.4 s, depending on when the probe falls. In total, 6.6 to 8.6 s pass between the cut and the change of state (four measurements).
What does .State.Health show for a running container?
The container carries a health state, which docker ps summarizes in parentheses and which docker inspect details. To see it, you need two containers: one with a probe and one without. The second uses releve-contrat:1.0-sans-healthcheck, the same image as the correct one without the HEALTHCHECK line, which you build first. Go back to the directory of the lesson, the one with the Dockerfile of the correct image, copy that Dockerfile to Dockerfile.1.0-sans-healthcheck, delete the HEALTHCHECK line from it, then build.
docker build -f Dockerfile.1.0-sans-healthcheck -t releve-contrat:1.0-sans-healthcheck .Then run the two containers, wait one second, and list them.
docker run -d --name m-a -e CANAL=x releve-contrat:1.0docker run -d --name m-f -e CANAL=x releve-contrat:1.0-sans-healthchecksleep 1docker ps --format 'table {{.Names}}\t{{.Image}}\t{{.Status}}'NAMES IMAGE STATUSm-f releve-contrat:1.0-sans-healthcheck Up 1 secondm-a releve-contrat:1.0 Up 1 second (healthy)The container without a probe only shows Up: nothing says whether it is working. The one that has a probe shows (healthy). Now read the detail, six seconds later.
sleep 5docker inspect --format '{{json .State.Health}}' m-adocker inspect --format '{{json .State.Health}}' m-f{"Status":"healthy","FailingStreak":0,"Log":[{"Start":"2026-11-03T13:37:38.253516787Z","End":"2026-11-03T13:37:38.459444892Z","ExitCode":0,"Output":""},{"Start":"2026-11-03T13:37:40.460098575Z","End":"2026-11-03T13:37:40.679210969Z","ExitCode":0,"Output":""},{"Start":"2026-11-03T13:37:42.680100657Z","End":"2026-11-03T13:37:42.905873651Z","ExitCode":0,"Output":""}]}nullThree fields are worth reading. Status gives the state. FailingStreak counts the consecutive failures, here 0. Log keeps the latest results of the probe (five entries at most), with their exit code (ExitCode) and their output. The three successful probes start a little more than 2 s apart, because the interval is counted from the end of the previous probe. For the image without a probe, .State.Health is null: that is what the script tests in order to reject an image without a HEALTHCHECK.
What happens when the work stops?
Delete the /data/source file in the m-a container, which stops the work, then read the state again twelve seconds later.
docker exec m-a python -c "import os; os.remove('/data/source')"sleep 12docker inspect --format '{{json .State.Health}}' m-adocker ps --format 'table {{.Names}}\t{{.Status}}'docker inspect --format 'running={{.State.Running}} restarts={{.RestartCount}} pid={{.State.Pid}}' m-aThe output of .State.Health is abridged here: the log keeps the last two successful probes then the three failing probes, with the Python trace of each.
{"Status":"unhealthy","FailingStreak":3,"Log":[{"Start":"2026-11-03T13:37:44.907568353Z","End":"2026-11-03T13:37:45.120684474Z","ExitCode":0,"Output":""},{"Start":"2026-11-03T13:37:47.121482637Z","End":"2026-11-03T13:37:47.338941123Z","ExitCode":0,"Output":""},{"Start":"2026-11-03T13:37:49.340973058Z","End":"2026-11-03T13:37:49.605037839Z","ExitCode":1,"Output":"Traceback (most recent call last):\n …\nurllib.error.HTTPError: HTTP Error 503: Service Unavailable\n"}, …]}NAMES STATUSm-f Up 18 secondsm-a Up 18 seconds (unhealthy)running=true restarts=0 pid=484411Read three things. The log explains why: the probe returned code 1, and its output ends with HTTP Error 503: Service Unavailable, the answer of /travail. The state goes to unhealthy and FailingStreak is 3 at the time of reading. Above all, the container keeps running: running=true, restarts=0. Docker reports the problem, but it does not restart the container. It is the orchestrator or the test script that reads this state and decides.
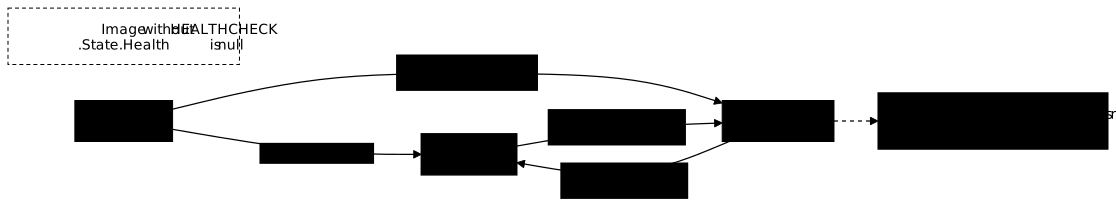
The following diagram sums up these states and what makes them change. Follow the arrows: a probe that succeeds leads to healthy, retries failures in a row lead to unhealthy, and the dotted arrow recalls that no restart follows. Set apart, the image without a probe has no state at all: .State.Health is null.
How do you override or disable the probe of an image?
At launch, two options replace the probe of the image: --health-cmd to supply another one, --no-healthcheck to remove it. They are used to test an image without rebuilding it. Here is the override that always fails, with an interval of one second and a single tolerated failure.
docker run -d --name m-s --health-cmd 'exit 1' --health-interval 1s --health-retries 1 -e CANAL=x releve-contrat:1.0sleep 4docker inspect --format '{{json .Config.Healthcheck}} {{.State.Health.Status}}' m-s{"Test":["CMD-SHELL","exit 1"],"Interval":1000000000,"Timeout":1000000000,"StartPeriod":3000000000,"StartInterval":500000000,"Retries":1} unhealthyThe command and the options given replace those of the image (CMD-SHELL, Interval, Retries), but the fields that are not given again, Timeout, StartPeriod and StartInterval, keep the value from the Dockerfile. With --no-healthcheck, the test becomes ["NONE"] and the health state disappears.
docker run -d --name m-n --no-healthcheck -e CANAL=x releve-contrat:1.0docker inspect --format '{{json .Config.Healthcheck}} {{json .State.Health}}' m-n{"Test":["NONE"],"Interval":2000000000,"Timeout":1000000000,"StartPeriod":3000000000,"StartInterval":500000000,"Retries":2} nullOne last point about the probe of the image: it is copied into the container when it is created. After you change the HEALTHCHECK and rebuild the image, a container that already exists keeps the old probe; you have to delete it and recreate it with docker run for the new one to apply. With Compose, docker compose up itself recreates the service whose image has changed, without having to add --force-recreate.
Remove the containers of this section before going on.
docker rm -f m-a m-f m-s m-nHow does the script start the image and wait without a fixed delay?
A test that sleeps for two seconds then queries the service fails on a slow machine and wastes time on a fast one. The script replaces each fixed pause with a bounded loop: it polls, exits as soon as the condition is true, and stops with a failure at a limit. The file starts with the common protocol, then two wait functions.
#!/usr/bin/env bash# Usage: tester-contrat.sh <image>set -euo pipefailimage="${1:?usage: $0 <image>}"pref="tc-$$"refuser() { echo "REFUSE [$1] $2"; exit 1; }ok() { echo "ok     [$1] $2"; }nettoyer() { docker rm -f "$pref-a" "$pref-b" "$pref-c" "$pref-d" >/dev/null 2>&1 || true; }trap nettoyer EXIT
# --- Parts specific to the releve-contrat service: adapt them to your image ---donnees=/data                      # writable data folderfichier_travail="$donnees/source"  # file on which the service's work depends# The image must also provide `id` and `python`, used with `docker exec` below.# --- End of the service-specific parts ---
port_de() {  local p  p=$(docker port "$1" 8080/tcp | head -n 1)  echo "${p##*:}"}# attendre_pret <container> <limit in s>: prints the duration, fails otherwiseattendre_pret() {  local nom="$1" limite="$2" debut fin etat port  debut=$(date +%s.%N)  port=$(port_de "$nom")  while true; do    if curl -fs --max-time 1 "http://127.0.0.1:$port/pret" >/dev/null 2>&1; then      fin=$(date +%s.%N)      awk -v a="$debut" -v b="$fin" 'BEGIN{printf "%.2f", b-a}'      return 0    fi    etat=$(docker inspect --format '{{.State.Running}}' "$nom")    [ "$etat" = "true" ] || return 2    fin=$(date +%s.%N)    awk -v a="$debut" -v b="$fin" -v l="$limite" 'BEGIN{exit !(b-a>l)}' && return 1    sleep 0.2  done}# attendre_sante <container> <expected> <limit>: polls the state, with no fixed delayattendre_sante() {  local nom="$1" attendu="$2" limite="$3" debut fin etat  debut=$(date +%s.%N)  while true; do    etat=$(docker inspect --format '{{.State.Health.Status}}' "$nom")    [ "$etat" = "$attendu" ] && return 0    fin=$(date +%s.%N)    awk -v a="$debut" -v b="$fin" -v l="$limite" 'BEGIN{exit !(b-a>l)}' && return 1    sleep 0.5  done}
# --- sante (declaration) ---hc=$(docker inspect --format '{{json .Config.Healthcheck}}' "$image")[ "$hc" != "null" ] || refuser sante "no HEALTHCHECK declared in the image"sonde=$(docker inspect --format '{{json .Config.Healthcheck.Test}}' "$image")[ "$sonde" != '["NONE"]' ] || refuser sante "HEALTHCHECK NONE: the image's probe is disabled"ok sante "HEALTHCHECK declared"
Save this block as tester-contrat.sh and run it right away on the correct image: the file only contains the declaration of the probe so far, so a single line is displayed.
bash tester-contrat.sh releve-contrat:1.0ok [sante] HEALTHCHECK declaredOn an image built without the HEALTHCHECK line, the same file writes REFUSE [sante] no HEALTHCHECK declared in the image. On an image whose Dockerfile carries HEALTHCHECK NONE instead, it writes REFUSE [sante] HEALTHCHECK NONE: the image's probe is disabled, and it returns code 1 in both cases.
The start of the file sets the protocol. refuser writes REFUSE [check] message then exits with code 1, ok writes a success line, and the trap nettoyer EXIT instruction deletes the test containers whatever the result, including after a rejection. The containers carry the tc- prefix followed by the PID of the script ($$), so that two simultaneous runs do not collide.
The containers are started with -p 127.0.0.1::8080: Docker itself picks a free port on the host, and port_de reads it back with docker port. No port is hard-coded, so there is no collision with another service on the machine.
attendre_pret returns three distinct results: 0 if /pret answers (and it then prints the duration), 1 if the limit is reached, 2 if the container stopped during the wait. The script calls these functions with || rc=$? or || refuser: the assignment then the test, the gesture from the lesson on the multi-stage build, keeps set -e from cutting the script before the rejection message is written. attendre_sante does the same for the health state, which it reads with docker inspect --format '{{.State.Health.Status}}'.
The last lines of the block take up the section on health: an image whose .Config.Healthcheck is null is rejected before it is even run, and so is an image whose test is ["NONE"] (HEALTHCHECK NONE in the Dockerfile, which disables the probe), with a message that says so.
The block of variables placed after the trap gathers what is specific to the demonstration service: the data folder, the file on which the work depends, and the presence of id and python in the image. Everything else in the script holds for any image that exposes /pret on port 8080. The tester-contrat.sh file is obtained by pasting, in order, the code blocks of the sections on configuration, startup, permissions, health and shutdown after this one: five blocks to paste, one per section.
How do you test the configuration?
A container whose configuration is badly supplied must stop quickly and say which one. The script tests both cases: the required variable missing, then an optional variable given. Add these two checks at the end of the file.
# --- configuration: required variable missing ---docker run -d --name "$pref-c" "$image" >/dev/nullcode=$(timeout 20 docker wait "$pref-c" || echo timeout)[ "$code" != "0" ] || refuser configuration "without CANAL, the container stopped with code 0 (or did not check)"[ "$code" != "timeout" ] || refuser configuration "without CANAL, the container is still running: the required variable is not checked"journal=$(docker logs "$pref-c" 2>&1 | head -n 5)case "$journal" in *CANAL*) ;; *) refuser configuration "code $code but no message names CANAL" ;; esacok configuration "CANAL missing: stopped with code $code and a clear message"
# --- configuration: optional variable ---docker run -d --name "$pref-d" -e CANAL=essai -e CADENCE=2 -p 127.0.0.1::8080 "$image" >/dev/nulld=$(attendre_pret "$pref-d" 15) || refuser configuration "the container with CADENCE=2 does not answer"rep=$(curl -s --max-time 2 "http://127.0.0.1:$(port_de "$pref-d")/pret")case "$rep" in *cadence=2*) ;; *) refuser configuration "CADENCE=2 ignored (answer: $rep)" ;; esacok configuration "CADENCE=2 taken into account"
The first check runs the image without CANAL and waits for it to end with docker wait, bounded to 20 s by timeout. Three defects are told apart: a code 0 (the container stopped as if all was well), an overrun of the 20 s (it keeps running although it lacks what it needs), and a stop on error whose logs do not name the variable. The script accepts any non-zero code, not only 78: the contract says "fail", not "fail with this number".
The second check gives CADENCE=2 and verifies that /pret answers cadence=2. A variable that the program ignores would show up this way, although it makes no startup fail.
How do you test startup and operation?
Startup is measured from the launch to the first answer of /pret, with a 15 s limit. Operation then verifies that the two routes answer what is expected, and not merely that they answer.
# --- demarrage ---docker run -d --name "$pref-a" -e CANAL=essai -p 127.0.0.1::8080 "$image" >/dev/nullrc=0duree=$(attendre_pret "$pref-a" 15) || rc=$?[ "$rc" -eq 0 ] || refuser demarrage "the service does not answer within 15 s (code $rc)"ok demarrage "answers in ${duree} s"
# --- fonctionnement ---port=$(port_de "$pref-a")rep=$(curl -s --max-time 2 "http://127.0.0.1:$port/pret")case "$rep" in "pret canal=essai"*) ;; *) refuser fonctionnement "unexpected answer on /pret: $rep" ;; esactrav=$(curl -s -o /dev/null -w '%{http_code}' --max-time 2 "http://127.0.0.1:$port/travail")[ "$trav" = "200" ] || refuser fonctionnement "/travail returns $trav instead of 200"ok fonctionnement "/pret and /travail answer as expected"
The tc-…-a container started here serves the following checks: permissions, health and shutdown. The return code of attendre_pret is kept in rc and shown in the message, which tells an exceeded limit (1) from a container that stopped (2). For the correct image, the script prints a duration of about 0.3 s, which depends on the machine: it is there to spot a drift, not to set a threshold.
The operation check compares the content of the answer. /pret must announce canal=essai, proof that the variable given at launch did reach the program. curl -w '%{http_code}' reads the HTTP code of /travail without printing the body.
How do you test permissions?
Two checks cover the rights: the process is not root, and the image keeps working when its file system is read-only.
# --- permissions ---uid=$(docker exec "$pref-a" id -u)[ "$uid" != "0" ] || refuser permissions "the process runs with uid 0 (root)"ok permissions "uid $uid, not root"docker run -d --name "$pref-b" --read-only --tmpfs "$donnees:uid=$uid,gid=$uid" -e CANAL=essai -p 127.0.0.1::8080 "$image" >/dev/nullrc=0attendre_pret "$pref-b" 15 >/dev/null || rc=$?[ "$rc" -eq 0 ] || refuser permissions "the service does not run under --read-only with a tmpfs on /data (code $rc)"if docker exec "$pref-b" python -c "open('/tmp/intrus','w')" >/dev/null 2>&1; then refuser permissions "writing to /tmp is possible under --read-only: the file system is not read-only"fiok permissions "--read-only: the service runs, writing outside /data is refused"With the configuration, startup and permissions blocks pasted at the end of the file, the script gives this on the correct image. The durations vary from one run to the next.
bash tester-contrat.sh releve-contrat:1.0ok [sante] HEALTHCHECK declaredok [configuration] CANAL missing: stopped with code 78 and a clear messageok [configuration] CADENCE=2 taken into accountok [demarrage] answers in 0.27 sok [fonctionnement] /pret and /travail answer as expectedok [permissions] uid 10001, not rootok [permissions] --read-only: the service runs, writing outside /data is refusedThe first check runs id -u with docker exec: it reads the uid of the user configured for a new process of the container (here the one from USER), not that of PID 1. It rejects uid 0. The script tests "other than 0" rather than "equal to 10001": the contract is not to be root, not to carry a particular number. To understand why USER must come after the instructions that write, read the lesson on USER.
The second check runs the image again with --read-only, which makes the whole file system of the container non-writable, except /data, mounted as tmpfs (a folder kept in memory) and owned by the uid read by the first check (10001 here). The image must start anyway: it therefore only writes in the folder it declares. The script then tries to write to /tmp/intrus, a path that uid 10001 can write when --read-only is absent and that is not under /data; under --read-only, the kernel answers Errno 30 (read-only file system) and the write fails. Writing to /app would prove nothing: that folder belongs to root, so the write is already refused to uid 10001 without --read-only (Errno 13, permission denied).
This check prevents an operations outage: an application that writes in its own folder stops starting as soon as the operator mounts the container read-only. A rejection of this check followed by (code 2) means that the container stopped during the wait.
How do you test the health state?
Declaring a HEALTHCHECK is not enough: the probe must follow the work. The script checks this with a complete cycle, healthy, sick, healthy, by acting on the container from the outside.
# --- sante (behavior) ---attendre_sante "$pref-a" healthy 20 || refuser sante "the image did not become healthy within 20 s"ok sante "healthy"docker exec "$pref-a" python -c "import os; os.remove('$fichier_travail')"attendre_sante "$pref-a" unhealthy 20 || refuser sante "the work has stopped but the image is still healthy after 20 s (the probe does not measure the work)"ok sante "unhealthy when the work stops"docker exec "$pref-a" python -c "open('$fichier_travail','a').close()"attendre_sante "$pref-a" healthy 20 || refuser sante "the work has resumed but the image did not become healthy again"ok sante "back to healthy"Once this block is pasted in turn, three lines are added, one per step of the cycle.
[...]ok [permissions] --read-only: the service runs, writing outside /data is refusedok [sante] healthyok [sante] unhealthy when the work stopsok [sante] back to healthyThe script first waits for healthy, then deletes the work file (/data/source here), the gesture that stops the work, and waits for unhealthy for 20 s at most. It then recreates the file and waits for the return to healthy. An image whose probe only looks at whether the process answers will never go to unhealthy: the script then rejects it with the message that says the probe does not measure the work.
The 20 s limit leaves a margin over the values of the image (2 s interval, 2 failures, five rates of one second for the work to be judged too old). If you lengthen the interval of the probe, lengthen this limit with it.
How do you test shutdown?
Shutdown is tested with the command the user will type, docker stop, by measuring the time it takes and the exit code that results. Add the last check, which concludes the script.
# --- arret ---t0=$(date +%s.%N)docker stop "$pref-a" >/dev/nullt1=$(date +%s.%N)duree=$(awk -v a="$t0" -v b="$t1" 'BEGIN{printf "%.2f", b-a}')sortie=$(docker inspect --format '{{.State.ExitCode}}' "$pref-a")case "$sortie" in 0|143) ;; *) refuser arret "exit code $sortie after docker stop in ${duree} s (SIGTERM not handled?)" ;; esacawk -v d="$duree" 'BEGIN{exit !(d<8)}' || refuser arret "stop took ${duree} s, too close to the 10 s grace period"ok arret "code $sortie in ${duree} s"echo "ACCEPT $image"docker stop sends SIGTERM, waits ten seconds by default, then sends SIGKILL. Two code values are accepted: 0, when the program handles the signal and exits cleanly, and 143, that is 128 + 15, when the program is not PID 1, for example behind docker run --init, and is terminated by SIGTERM for lack of a handler. In exec form and without a handler, it is on the contrary PID 1 that ignores SIGTERM: Docker kills it at the end of the delay and the container ends with 137, that is 128 + 9 (SIGKILL). The mechanisms are explained in Container lifecycle, PID 1 and clean shutdown in Docker.
The second test is about duration: a stop that lasts almost ten seconds, even with a code 0, signals an image that waits for the grace period. The 8 s threshold is a choice of the script, not a Docker rule; adjust it to your service. The last line, ACCEPT, is only reached if all the checks have succeeded.
What does the script give on the correct image?
Run the script on the releve-contrat:1.0 image, then read the exit code.
bash tester-contrat.sh releve-contrat:1.0echo "code=$?"ok [sante] HEALTHCHECK declaredok [configuration] CANAL missing: stopped with code 78 and a clear messageok [configuration] CADENCE=2 taken into accountok [demarrage] answers in 0.27 sok [fonctionnement] /pret and /travail answer as expectedok [permissions] uid 10001, not rootok [permissions] --read-only: the service runs, writing outside /data is refusedok [sante] healthyok [sante] unhealthy when the work stopsok [sante] back to healthyok [arret] code 0 in 0.52 sACCEPT releve-contrat:1.0code=0Eleven checks pass and the exit code is 0. The complete run took 14.4 s from start to finish on the machine of the lesson, a duration that depends on the machine. The values to look at are 78, the code the program returns without CANAL, and 0 at shutdown: the image handles SIGTERM in 0.52 s.
How do you build broken images, and what does the script reject?
A test that has never rejected any image proves nothing: you do not know whether it sees the defects or always says yes. Six images differ from the good one by only one small deviation each. For each variant, copy the Dockerfile of the correct image to Dockerfile.<label> and apply the deviation from the table, then build with docker build -f Dockerfile.<label> -t releve-contrat:<label> ..
| Label | Deviation from the correct Dockerfile | Contract defect |
|---|---|---|
1.0-root | the USER 10001 line is deleted | the program runs as root |
1.0-sigterm | CMD in shell form: CMD python /app/releve.py; exit $? | SIGTERM does not reach the program |
1.0-sante-processus | the probe calls /pret instead of /travail | the health state does not depend on the work |
1.0-ecrit-hors | RUN touch /app/journal.log && chown 10001 /app/journal.log before USER, and ENV JOURNAL=/app/journal.log after | the program writes outside /data |
1.0-sans-controle | ENV CANAL=defaut added after USER | the required variable has a hidden default value |
1.0-sans-healthcheck | the HEALTHCHECK line is deleted | no probe |
The order of 1.0-ecrit-hors matters: the RUN touch runs as root, before USER, otherwise the build fails (see the troubleshooting section). Now run the same script on each image and read the first rejection.
The image that runs as root
bash tester-contrat.sh releve-contrat:1.0-rootok [sante] HEALTHCHECK declaredok [configuration] CANAL missing: stopped with code 78 and a clear messageok [configuration] CADENCE=2 taken into accountok [demarrage] answers in 0.28 sok [fonctionnement] /pret and /travail answer as expectedREFUSE [permissions] the process runs with uid 0 (root)Five checks pass and the sixth rejects. This image starts, answers and configures itself: a test of the application code would call it good. Only the contract on the uid blocks it. The script returned code 1 after 2.1 s.
The image that ignores SIGTERM
bash tester-contrat.sh releve-contrat:1.0-sigtermok [sante] HEALTHCHECK declaredok [configuration] CANAL missing: stopped with code 78 and a clear messageok [configuration] CADENCE=2 taken into accountok [demarrage] answers in 0.27 sok [fonctionnement] /pret and /travail answer as expectedok [permissions] uid 10001, not rootok [permissions] --read-only: the service runs, writing outside /data is refusedok [sante] healthyok [sante] unhealthy when the work stopsok [sante] back to healthyREFUSE [arret] exit code 137 after docker stop in 10.29 s (SIGTERM not handled?)All the checks pass except the last, which is the only one able to see this defect. With a command followed by ; exit $?, the shell form of CMD leaves a shell as PID 1, and that shell does not forward SIGTERM to the Python program: Docker waits for the ten seconds of the grace period before killing the container. The script measured 137 after 10.29 s, and it returned code 1 after 22.1 s in all. These durations are a measurement on the machine of the lesson (the measurements of the forced stop range from 10.21 to 10.30 s): remember the order of magnitude, the grace period of ten seconds.
The image has no ps, but the kernel exposes the command line of PID 1 in /proc. Read it in a container started with this image.
docker run -d --name m-sig -e CANAL=x releve-contrat:1.0-sigterm >/dev/nulldocker exec m-sig cat /proc/1/cmdline | tr '\0' ' '; echodocker rm -f m-sig >/dev/null/bin/sh -c python /app/releve.py; exit $?PID 1 must appear as /bin/sh -c python /app/releve.py; exit $?: it is the shell, not python, that receives SIGTERM. With the correct image, the same command prints python /app/releve.py.
The image whose probe does not measure the work
bash tester-contrat.sh releve-contrat:1.0-sante-processusok [sante] HEALTHCHECK declaredok [configuration] CANAL missing: stopped with code 78 and a clear messageok [configuration] CADENCE=2 taken into accountok [demarrage] answers in 0.27 sok [fonctionnement] /pret and /travail answer as expectedok [permissions] uid 10001, not rootok [permissions] --read-only: the service runs, writing outside /data is refusedok [sante] healthyREFUSE [sante] the work has stopped but the image is still healthy after 20 s (the probe does not measure the work)This image does have a HEALTHCHECK, and the declaration check let it through. Its probe queries /pret, which answers as long as the process runs, so it stays healthy although the work has stopped. This defect is sneaky: the health state is green and wrong. Only the complete cycle of the health check unmasks it, in 23.2 s.
The image that writes outside its folder
bash tester-contrat.sh releve-contrat:1.0-ecrit-horsok [sante] HEALTHCHECK declaredok [configuration] CANAL missing: stopped with code 78 and a clear messageok [configuration] CADENCE=2 taken into accountok [demarrage] answers in 0.28 sok [fonctionnement] /pret and /travail answer as expectedok [permissions] uid 10001, not rootREFUSE [permissions] the service does not run under --read-only with a tmpfs on /data (code 2)In normal use, this image works: the /app/journal.log file belongs to uid 10001 and the program writes to it. Under --read-only, the write fails, the container stops, and attendre_pret returns code 2. The rejection appears in 2.8 s. This is the outage that the operator discovers the day they harden the image, and that this check makes visible before delivery.
The image that does not check its configuration
bash tester-contrat.sh releve-contrat:1.0-sans-controleok [sante] HEALTHCHECK declaredREFUSE [configuration] without CANAL, the container is still running: the required variable is not checkedWith ENV CANAL=defaut, the required variable is never missing: the program starts without the user having chosen a channel, and the container does not stop. The script waits 20 s for the container to end, then rejects (20.5 s in all). A default value hidden in the image leaves the configuration unchecked, which the contract forbids for a variable declared as required.
The image without a probe
bash tester-contrat.sh releve-contrat:1.0-sans-healthcheckREFUSE [sante] no HEALTHCHECK declared in the imageThe rejection is immediate: the script reads .Config.Healthcheck, finds null and stops before starting a single container, in under 0.1 s as measured.
The protocol is the same for all seven images: one command, one exit code, one line that names the check. Adding a check means adding a block to the script, without changing the way it is called.
Why does hadolint reject a duration in milliseconds?
hadolint, the static analyzer for Dockerfiles, only accepts the units s, m and h in the durations of a HEALTHCHECK, whereas Docker Engine also accepts ms. A Dockerfile written with --start-interval=500ms therefore builds without error, then fails the analysis with missing whitespace. The remedy is to write the duration in seconds: 0.5s, as in the Dockerfile of the lesson.
Go back to the directory of the lesson, the one that contains the Dockerfile of the correct image: the sed command below reads it by name. The docker run command that follows pins the hadolint version by its digest and cuts the network: the result depends neither on an update nor on outside access. It reads the Dockerfile of the correct image, which carries 0.5s.
docker run --rm -i --network none hadolint/hadolint:v2.15.1@sha256:32dac94127fd60b7b7e3fbfc65e1383b9b5e25c9bfd7b8536de7a539fe68a12d hadolint - < Dockerfileecho "rc=$?"rc=0Code 0 means the analysis passes. To see the rejection, give hadolint the same Dockerfile with the duration in milliseconds, in a temporary file.
sed 's/--start-interval=0.5s/--start-interval=500ms/' Dockerfile > Dockerfile.msdocker run --rm -i --network none hadolint/hadolint:v2.15.1@sha256:32dac94127fd60b7b7e3fbfc65e1383b9b5e25c9bfd7b8536de7a539fe68a12d hadolint - < Dockerfile.msecho "rc=$?"rm Dockerfile.ms/dev/stdin:8:79 missing whitespacerc=1Look at column 79: it points to the end of 500ms. The analyzer reads 500m as 500 minutes, then the remaining s matches no field, hence "missing whitespace". It is a parsing error, not a style rule that --ignore could turn off. Versions 2.14.0 (image hadolint/hadolint:v2.14.0@sha256:27086352fd5e1907ea2b934eb1023f217c5ae087992eb59fde121dce9c9ff21e) and 2.15.1 of hadolint both reject 500ms, with the same message and the same columns.
| Duration tested | Option | Exit code |
|---|---|---|
500ms | --start-interval | 1 (missing whitespace) |
1s | --start-interval | 0 |
0.5s | --start-interval | 0 |
2s | --start-interval | 0 |
500ms | --interval | 1 (missing whitespace, column 28) |
The table shows that --start-interval is recognized: only the ms unit is a problem, including on --interval, which is nothing new. So write all the HEALTHCHECK durations in s, m or h. Docker records 0.5s as "StartInterval":500000000, the same value as 500ms. The hadolint reference sheet (in French) describes the rules and the CI integration.
What should you do when a check rejects or the script fails?
Each row of the table takes up a message that Docker, hadolint or the script really display.
| Symptom | Cause | Solution |
|---|---|---|
error: no such object: releve-contrat:1.0-ecrit-hors | the image does not exist: the build failed or the label is misspelled | docker image ls releve-contrat; run docker build again and read its error |
RUN touch … did not complete successfully: exit code: 1 during the build | the RUN is placed after USER 10001: an unprivileged user cannot create a file in /app | place the RUN that writes before USER, then give the file to the uid with chown |
REFUSE [configuration] … the container stopped with code 0 | the program refuses to start, but a wrapper hides its exit code (for example a ; true before exit $? in shell form) | return the program's code as it is, in exec form |
REFUSE [permissions] … (code 2) | the container stops under --read-only: the program writes outside the intended folder | read docker logs, move the write into /data or mount a tmpfs at the right place |
REFUSE [sante] … is still healthy after 20 s | the probe queries a route that does not depend on the work | point the probe at /travail, or at the check that judges the real result |
Up … (unhealthy) and the container does not move | Docker does not restart an unhealthy container | read .State.Health.Log, fix the cause, or leave the decision to an orchestrator |
REFUSE [arret] exit code 137 … in 10.29 s | SIGTERM does not reach the program | exec form for CMD, or a signal handler in the program |
/dev/stdin:8:79 missing whitespace with hadolint | a HEALTHCHECK duration is written in milliseconds (500ms), a unit that hadolint does not accept | write the duration in seconds (0.5s), see the section on milliseconds |
When a rejection is not enough, run the container in question again by hand, because the trap deletes the test containers when the script exits, then read docker logs. The page Inspect a running container with Docker gives the detail of the fields to look at.
How do you clean everything up?
The test script already deletes its containers with trap. What remains is the images built, the hadolint image and the build cache, where BuildKit keeps the python:3.15.2-slim base image: it does not appear in docker image ls, so docker image rm cannot remove it. Remove the images by their exact name, empty the cache with docker builder prune --all --force (it erases the cache of all your builds, not only that of this lesson), and delete the files of the lesson by name, without recursive deletion.
docker rm -f m-a m-f m-s m-n hc-long hc-court 2>/dev/nulldocker image rm sonde-lente:1.0 releve-contrat:1.0 releve-contrat:1.0-root releve-contrat:1.0-sigterm \ releve-contrat:1.0-sante-processus releve-contrat:1.0-ecrit-hors \ releve-contrat:1.0-sans-controle releve-contrat:1.0-sans-healthcheckdocker builder prune --all --forcedocker image rm hadolint/hadolint:v2.15.1@sha256:32dac94127fd60b7b7e3fbfc65e1383b9b5e25c9bfd7b8536de7a539fe68a12ddocker ps -aFor the files, rm releve.py Dockerfile tester-contrat.sh and each Dockerfile.<label> that you created, then rmdir on the working directory. In the slow probe directory, rm sonde.sh Dockerfile, then rmdir. Check that docker ps -a no longer lists any container of the lesson.
Practice
The lab provides a Dockerfile and a service to build: the resulting container always shows "Up", even when its work is stopped. You add a health probe that judges the real work rather than the presence of the process, then you cause the three states: healthy at the start, sick when the work stops, healthy again when it resumes. Only the state of the system is checked, with dsoxlab check, never the commands typed: the validation reads the probe declared in the image and its time bounds, then observes the health state of the container at each step.
Key points
-
The contract of an image is what a user can expect without reading its Dockerfile: start, answer, be configured, run without privilege, stop, report its state. Each expectation becomes a check, run from the outside on the final image.
-
A test script bounds every wait: a loop that exits as soon as the condition is true and fails at a limit, never a fixed pause. Each rejection writes
REFUSE [check] messageand returns code 1. -
For a missing required variable, the image must stop with a non-zero code and a message that names the variable. A default value hidden in the image makes that requirement ineffective.
-
Check the uid with
docker exec … id -uand run the image again with--read-onlyand atmpfson the data folder: an image that writes elsewhere stops under--read-only. -
docker stopsends SIGTERM then SIGKILL after ten seconds. A code 137, returned at the end of the grace period (10 s by default; 10.29 s measured here), signals an image that ignores SIGTERM; 0 or 143 is acceptable. -
HEALTHCHECKis written in the Dockerfile and read in.Config.Healthcheck, in nanoseconds, then.State.Healthand itsLog. Anunhealthycontainer keeps running;--health-cmdoverrides the probe and--no-healthcheckremoves it. -
A probe must judge the work, not the process. The test that cuts the work and waits for
unhealthy, thenhealthyon the return, is the only one that unmasks an always-green probe. -
hadolint only accepts the units
s,mandhin the durations of aHEALTHCHECK, whereas Docker 29.9.2 also acceptsms: write0.5srather than500msto avoidmissing whitespace.
Knowledge check
Check that the essentials of this lesson have stuck. The questions cover only what has just been explained here.
Knowledge check
Check what you have learned with this interactive quiz
How it works
- The timer starts when you click Start
- Multiple choice, true/false and short answer questions
- You can move between questions
- Detailed results are shown at the end
Starts the quiz and the timer
Review
(0/0)Score by domain
A domain groups several guides and gets several questions, so its score is more reliable than a per-topic score, which often rests on a single question.
Summary
Strengths
No topic passed at 80% on at least two questions yet.
Weak areas
No topic below the pass mark.
Recommended next
Hints before you try again?
Continue the course: Inspect and shrink a Docker image without breaking it
A new full quiz with random questions
Work again only on the questions you missed