A published port does not answer, or answers only to some clients, and the temptation is to flush the firewall "to see". This lesson teaches you the opposite: locate the faulty hop with probes placed at each step of the path and with rule counters, fix a single rule, then prove the fix with tests that succeed and tests that still fail. The measurements come from a throwaway Debian 13 VM with Docker Engine 29.9.2 and iptables 1.8.11 (nf_tables): they describe this engine and this firewall, not every host.
What you will learn
Each diagnosis ends with a measurement, never with a guess.
- You follow the path of a packet to a published port, from the DNAT to the container, and you tell routed traffic from the host's local traffic.
- You read the firewall that Docker really uses with
docker info, then the nftables tables that coexist with its own. - You probe a multi-hop flow and you read a rule's counters to know whether it sees the packets.
- You explain why a
DOCKER-USERrule written on the published port blocks nothing, and you fix it with--ctorigdstport. - You spot a host firewall placed in another nftables table, you measure that an
ACCEPTinDOCKER-USERdoes not override its refusal, you insert a targeted rule at the right place and you roll back. - You read the MTU at each hop and you probe it with a
pingthat sets the DF bit.
Prerequisites
This lesson builds on two lessons: Publish a Docker port without exposing the
whole host and Default Docker network or your
own: which to choose?. You must
know how to publish a port with -p, create a network with docker network create and read an IP address and a mask such as 172.31.10.0/24.
You need a disposable machine: a Linux VM with Docker Engine installed from
the official repository, sudo access, curl, the nft command (package
nftables) and the iputils ping, the one shipped with current Debian and
Ubuntu. Also check iptables --version: it must display nf_tables. If the
version is legacy, Docker's rules are not in nftables and nft list tables
does not show them.
Do not replay these commands on a shared host or in production: they add rules to the firewall, and one of them cuts the host's routed traffic. The section "How do you roll back in an emergency?" gives the commands that remove everything.
All the containers of the demonstration start from the same Alpine image, pinned
to its digest. BusyBox provides nc, wget and nslookup there, but no HTTP
server: the c39-m-api container therefore answers with nc, in a loop, with
the string api-c39. The objects created carry the prefix c39-m- and
172.31.x.0/24 networks, which lets you remove everything without touching the
rest. The names of the containers and the labels of the probes are in French,
kept as is in the listings: hote is the host, voisin the neighbour,
partenaire the partner, intrus the intruder, sonde a probe.
Which path does a packet take to a container?
A client that reaches host:8070 does not talk to the container directly: the
kernel first rewrites the destination, then passes the packet through chains of
rules. Netfilter is the Linux kernel's filtering framework; iptables and
nftables are two tools that write rules into it. A base chain is a chain
attached to a precise point of the path, called a hook: it is the one that
receives the packets, the other chains being only subroutines it calls.
DNAT (Destination NAT) replaces the destination address and port of an
incoming packet. For a published port, Docker adds this DNAT in the nat table,
before the kernel decides to route the packet to the container. The packet then
enters the FORWARD hook, the one for traffic that crosses the host without
being addressed to it. The rules you write in DOCKER-USER are read there
first, then those of DOCKER-FORWARD, which Docker manages. Another nftables
table of the host, whose priority is higher than filter (for example filter + 10), is evaluated after Docker's. filter is here the name of Docker's
priority, which is 0, and not that of a chain.
Traffic from a host process to 127.0.0.1 follows another path: the DNAT does
not apply to the loopback, and it is docker-proxy, a host process, that
receives the connection and opens another one to the container. The lesson
Publish a Docker port without exposing the whole
host teaches this mechanism. In the diagram
below, the thick line follows an external client and the dotted line the host
process that targets 127.0.0.1.
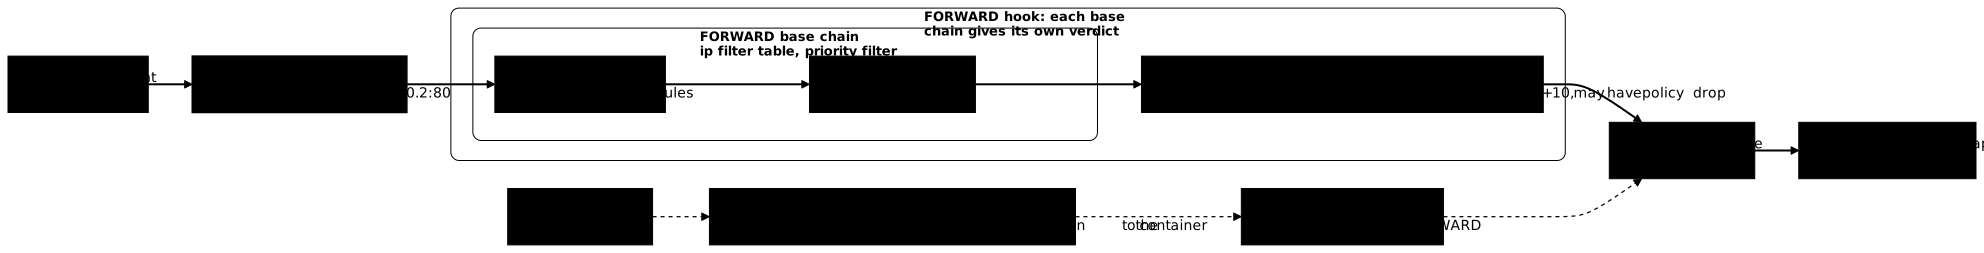
Docker's documentation on iptables rules describes these chains. The guide on NAT (in French) details the DNAT and the kernel's connection tracking, the guide on the firewall (in French) covers filtering in general, and the one on nftables covers the tool that writes into the tables.
Which firewall does Docker really use?
Before reading rules, you must know where they are. A host can expose the
iptables command while writing into nftables, and Docker chooses its own rules
engine. The following commands record the state of the host before any
container of the demonstration: the engine version, the firewall Docker
announces, the iptables version, all the nftables tables (not only
Docker's), the FORWARD chain, the DOCKER-USER chain, Docker's NAT and the
docker0 bridge.
docker version --format 'serveur={{.Server.Version}}'docker info --format 'Firewall={{.FirewallBackend.Driver}}'sudo iptables --versionsudo nft list tablessudo iptables -S FORWARDsudo iptables -S DOCKER-USERsudo iptables -t nat -S | grep -E 'DOCKER|MASQUERADE'ip -br addr show docker0docker ps -aq | wc -lserveur=29.9.2Firewall=iptablesiptables v1.8.11 (nf_tables)table ip nattable ip filtertable ip6 nattable ip6 filtertable ip raw-P FORWARD DROP-A FORWARD -j DOCKER-USER-A FORWARD -j DOCKER-FORWARD-N DOCKER-USER-N DOCKER-A PREROUTING -m addrtype --dst-type LOCAL -j DOCKER-A OUTPUT ! -d 127.0.0.0/8 -m addrtype --dst-type LOCAL -j DOCKER-A POSTROUTING -s 172.17.0.0/16 ! -o docker0 -j MASQUERADEdocker0 DOWN 172.17.0.1/160Read these outputs together. Docker announces the iptables backend, and
iptables is in its nf_tables version: the rules are written with the
iptables syntax but stored in nftables, which the ip nat and ip filter
tables in nft list tables confirm. The ip raw table already exists here,
although no container has been created. A host firewall written directly with
nftables would show up as an extra table in this list, which the section on the
host firewall stages.
Now look at three lines. The DROP policy of the FORWARD hook refuses
everything Docker does not explicitly accept. FORWARD calls DOCKER-USER
before DOCKER-FORWARD, and DOCKER-USER, empty here, is the place meant for
your rules. In the nat table, two rules send traffic to the DOCKER chain:
PREROUTING for packets that arrive from outside, OUTPUT for those the host
emits itself, but not those that target the loopback (127.0.0.0/8).
Published ports add their DNAT rules in this DOCKER chain.
One last reading places Docker relative to the other tables. The following
command displays the first four lines of the FORWARD chain as nftables stores
it.
sudo nft list chain ip filter FORWARD | sed -n 1,4ptable ip filter { chain FORWARD { type filter hook forward priority filter; policy drop; counter packets 105 bytes 20126 jump DOCKER-USERThe chain is attached to the forward hook with the filter priority. This
word is a priority name, which is 0. Another table whose chain carries filter + 10 therefore comes after Docker's, and filter - 10 would come before. The
counter's packet number is that of the measurement VM, read after the other
measurements of the lesson, hence its 105 packets: yours will be different.
The value Firewall=iptables is this host's. Other values exist depending on
the configuration: the host may use firewalld, and Docker 29 offers an nftables
backend, presented as experimental. The chains and names in this lesson are
those of the iptables backend measured here. If docker info announces
something else on your machine, first read Docker's documentation on the
iptables backend and
on the nftables
backend before
transposing.
How do you probe a flow across several hops?
A network failure is located by testing each hop separately, a hop being a
step of the path between the client and the service. You start with the one
closest to the target and work back toward the farthest. If hop n answers and
hop n+1 fails, the cause lies between the two. The demonstration builds four
containers on three networks: c39-m-api and c39-m-voisin share
c39-m-front, c39-m-partenaire lives on its own network, c39-m-intrus on a
third. Only c39-m-api publishes a port, the host's 8070 to its port 80.
The HOTE variable holds the IPv4 address of the Docker host, computed by the
command: it takes the machine's first global IPv4 address. If your machine has
several, check that it is the right one before going on, otherwise the partner
and intruder probes target the wrong interface.
ALP="alpine:3.24.3@sha256:be2656061b536c1883c4034790e21d0a09c5aaaf51968b89368a3c0371ea2c9a"HOTE=$(ip -4 -o addr show scope global | awk '{print $4}' | cut -d/ -f1 | head -1); echo "HOTE=$HOTE"SRV='while true; do printf "HTTP/1.0 200 OK\r\n\r\napi-c39\n" | nc -l -n -p 80; done'docker network create --subnet 172.31.10.0/24 c39-m-front >/dev/nulldocker network create --subnet 172.31.20.0/24 c39-m-partenaire >/dev/nulldocker network create --subnet 172.31.30.0/24 c39-m-intrus >/dev/nulldocker run -d --name c39-m-api --network c39-m-front -p 8070:80 "$ALP" sh -c "$SRV" >/dev/nulldocker run -d --name c39-m-voisin --network c39-m-front "$ALP" sleep 3600 >/dev/nulldocker run -d --name c39-m-partenaire --network c39-m-partenaire "$ALP" sleep 3600 >/dev/nulldocker run -d --name c39-m-intrus --network c39-m-intrus "$ALP" sleep 3600 >/dev/nulldocker port c39-m-apiThe first line displayed is the measurement VM's address, yours will be
different. The docker port command confirms the publication, on IPv4 and IPv6.
HOTE=10.10.130.1180/tcp -> 0.0.0.0:807080/tcp -> [::]:8070Two questions come up right away: who listens on the host's port 8070, and did the containers add nftables tables? The first command lists the sockets listening on this port with the process that holds them, the second rereads the kernel's tables.
sudo ss -ltnp 'sport = :8070' | tail -n +2 | awk '{print $4, $6}'sudo nft list tables0.0.0.0:8070 users:(("docker-proxy",pid=2407,fd=8))[::]:8070 users:(("docker-proxy",pid=2412,fd=8))table ip nattable ip filtertable ip6 nattable ip6 filtertable ip rawThe port is held by two docker-proxy processes, one on IPv4 (0.0.0.0) and
one on IPv6 (::). The tables are the five of the initial state: the containers
added no table. This docker-proxy explains why a test from the host to
127.0.0.1 proves nothing about a remote client. It receives the connection,
then opens another one to the container: that connection is emitted by the host
itself, so it does not cross FORWARD. A complementary measurement, made with a
service that logs the source address, confirms it: through 127.0.0.1, the
service sees 172.31.10.1, an address of the container's network; through the
host's address, the DNAT applies and it sees the host's address (10.10.130.11
on the measurement VM).
The first hop to probe is DNS. On a user-defined network, Docker provides a
built-in resolver at address 127.0.0.11 in every container. It resolves
container names only for the same network: a name that does not resolve from
another network is normal behavior, not a failure.
docker exec c39-m-voisin cat /etc/resolv.conf | grep nameserverdocker exec c39-m-voisin nslookup c39-m-api 2>&1 | grep -A1 'Name:'docker exec c39-m-partenaire nslookup c39-m-api 2>&1 | tail -2nameserver 127.0.0.11Name: c39-m-apiAddress: 172.31.10.2*** Can't find c39-m-api: No answerThe neighbour finds c39-m-api at address 172.31.10.2, the partner does not,
because it is on another network. For it to reach the API, you will therefore
have to go through the host's address and the published port, not through the
name. The next probes test six paths. The sonde function displays a label, the
return code (rc=0 if the command succeeded) and what the command answered.
Keep the same terminal: the following sections reuse this function and the
ALP, HOTE and SRV variables.
sonde() { printf '%-30s ' "$1"; shift; out=$("$@" 2>&1); echo "rc=$? ${out}" | tr '\n' ' '; echo; }sonde "hote -> 127.0.0.1:8070" curl -s -m 3 http://127.0.0.1:8070/sonde "hote -> 172.31.10.2:80" curl -s -m 3 http://172.31.10.2/sonde "voisin -> c39-m-api:80" docker exec c39-m-voisin wget -q -T 3 -O - http://c39-m-api/sonde "partenaire -> hote:8070" docker exec c39-m-partenaire wget -q -T 3 -O - "http://$HOTE:8070/"sonde "intrus -> hote:8070" docker exec c39-m-intrus wget -q -T 3 -O - "http://$HOTE:8070/"sonde "partenaire -> internet" docker exec c39-m-partenaire wget -q -T 5 -O /dev/null http://deb.debian.org/debian/hote -> 127.0.0.1:8070 rc=0 api-c39hote -> 172.31.10.2:80 rc=0 api-c39voisin -> c39-m-api:80 rc=0 api-c39partenaire -> hote:8070 rc=0 api-c39intrus -> hote:8070 rc=0 api-c39partenaire -> internet rc=0Before any rule, the six probes succeed: this is your baseline. The last one
displays rc=0 and nothing else, because wget writes to /dev/null. Each
probe crosses a different path. The neighbour stays on its network, without
going through the host. The host to 127.0.0.1 goes through docker-proxy. The
host to 172.31.10.2:80 reaches the container's address directly: it is one
more hop to test. The partner and the intruder play a remote client, because
their packets cross the same FORWARD hook as those of an outside machine. If a
failure appears later, the probe whose result changes points to the faulty hop.
Why does a DOCKER-USER rule on the published port block nothing?
You want to stop the c39-m-intrus network from reaching the API. The obvious
rule targets the port the intruder uses: 8070. It is written in DOCKER-USER,
the chain meant for the administrator's rules. The -I option inserts a
rule at the head of the chain, -A appends it at the end. The rule's counter
(pkts and bytes) tells how many packets it recognized: it is what tells you
whether the rule sees the traffic.
sudo iptables -I DOCKER-USER -s 172.31.30.0/24 -p tcp --dport 8070 -j DROPsonde "intrus -> hote:8070" docker exec c39-m-intrus wget -q -T 3 -O - "http://$HOTE:8070/"sudo iptables -L DOCKER-USER -n -v --line-numbersintrus -> hote:8070 rc=0 api-c39Chain DOCKER-USER (1 references)num pkts bytes target prot opt in out source destination1 0 0 DROP tcp -- * * 172.31.30.0/24 0.0.0.0/0 tcp dpt:8070The intruder still gets through, and the counter stays at 0 0: the rule has
never seen a packet. A counter at zero means the rule did not see the
packet, either because its criteria do not match, or because a decision was made
before it. Here it is the first case, and the cause can be read in the DOCKER
chain of the nat table.
sudo iptables -t nat -S DOCKER | grep 8070-A DOCKER ! -i br-51693c333467 -p tcp -m tcp --dport 8070 -j DNAT --to-destination 172.31.10.2:80The DNAT replaces host:8070 with 172.31.10.2:80 before the FORWARD
hook. When the packet reaches DOCKER-USER, its destination port is already 80
and its address is the container's: a rule that looks for --dport 8070 no
longer recognizes anything. The kernel nevertheless keeps the original
destination in its connection tracking, the conntrack, and iptables'
conntrack extension can read it with --ctorigdstport. The --ctdir ORIGINAL
option restricts the rule to packets going in the direction of the original
connection, from client to server, and not to the replies. The corrected rule
replaces the old one, then you replay the probes.
sudo iptables -D DOCKER-USER -s 172.31.30.0/24 -p tcp --dport 8070 -j DROPsudo iptables -I DOCKER-USER -s 172.31.30.0/24 -p tcp -m conntrack --ctorigdstport 8070 --ctdir ORIGINAL -j DROPsonde "intrus -> hote:8070" docker exec c39-m-intrus wget -q -T 3 -O - "http://$HOTE:8070/"sonde "partenaire -> hote:8070" docker exec c39-m-partenaire wget -q -T 3 -O - "http://$HOTE:8070/"sonde "hote -> 127.0.0.1:8070" curl -s -m 3 http://127.0.0.1:8070/sudo iptables -L DOCKER-USER -n -v --line-numbersintrus -> hote:8070 rc=1 wget: download timed outpartenaire -> hote:8070 rc=0 api-c39hote -> 127.0.0.1:8070 rc=0 api-c39Chain DOCKER-USER (1 references)num pkts bytes target prot opt in out source destination1 3 180 DROP tcp -- * * 172.31.30.0/24 0.0.0.0/0 ctorigdstport 8070 ctdir ORIGINALThe three probes form the proof. The negative test (the intruder fails, with
a download timed out because a DROP answers nothing) shows that the rule
blocks: the same probe succeeded before the rule. The positive tests (the
partner and the host succeed) show that it does not block those two flows. The
counter, now at 3 packets, proves that it is this rule that refused, and not
another hop. All three elements are needed: a failure alone can come from
elsewhere.
Removing the rule leaves the chain empty. The containers stay in place for the rest.
sudo iptables -D DOCKER-USER -s 172.31.30.0/24 -p tcp -m conntrack --ctorigdstport 8070 --ctdir ORIGINAL -j DROPsudo iptables -S DOCKER-USER-N DOCKER-USERWhat do you do when the host firewall blocks Docker?
A DOCKER-USER rule only weighs in Docker's chains. If the host has a firewall
written in nftables, in another table, its base chain on the FORWARD hook
is evaluated too, and Docker does not see it. To reproduce this, you set up a
c39_hote table (hote is French for host; the inet family covers IPv4 and
IPv6) whose forward chain has a drop policy: it refuses any packet that no
rule accepts, except replies to connections already established. A last counter drop rule refuses in the same way, with a counter that shows how many packets
get that far. The priority is the number that orders the base chains of a same
hook, the lowest first. With filter + 10, the chain therefore comes after
Docker's, whose priority is filter, as the reading of nft list chain ip filter FORWARD showed.
The demonstration reuses the topology of the previous section. Set up the host's table, then probe the host itself, the partner toward the API and the partner toward the internet.
cat > c39-hote.nft <<'EOF'table inet c39_hote { chain forward { type filter hook forward priority filter + 10; policy drop; ct state established,related accept counter drop }}EOFsudo nft -f c39-hote.nft; echo "nft_rc=$?"sonde "hote -> 127.0.0.1:8070" curl -s -m 3 http://127.0.0.1:8070/sonde "partenaire -> hote:8070" docker exec c39-m-partenaire wget -q -T 3 -O - "http://$HOTE:8070/"sonde "partenaire -> internet" docker exec c39-m-partenaire wget -q -T 5 -O /dev/null http://deb.debian.org/debian/nft_rc=0hote -> 127.0.0.1:8070 rc=0 api-c39partenaire -> hote:8070 rc=1 wget: download timed outpartenaire -> internet rc=1 wget: download timed outThis is the trap: the host answers itself, the partner gets nothing, and the
local test hides the failure because traffic to 127.0.0.1 does not cross
FORWARD. The partner no longer reaches the internet either, whereas the
baseline probe succeeded. Now ask Docker whether it reports a problem, and
reread all the tables.
docker info --format 'Firewall={{.FirewallBackend.Driver}}'sudo iptables -S DOCKER-USERsudo nft list tablesFirewall=iptables-N DOCKER-USERtable ip nattable ip filtertable ip6 nattable ip6 filtertable ip rawtable inet c39_hoteDocker announces its usual backend, and DOCKER-USER contains no rule:
nothing on Docker's side signals the refusal. The refusal comes from a table
that Docker does not manage, and only reading all the tables reveals it: the
inet c39_hote table appears next to Docker's.
That leaves the idea of working around the problem from Docker's side, by
accepting the flow in DOCKER-USER. It fails: each base chain of the hook
returns its own verdict. An accept only ends the chain that pronounces it, a
drop stops the packet: another table's drop therefore wins over a
DOCKER-USER ACCEPT. A measurement, at the end of this section, verifies it.
The fix is therefore made in the host's table, with a rule that accepts only
this flow: the destination after DNAT (172.31.10.2, port 80), restricted to
the original port 8070 by ct original proto-dst, the nftables equivalent of
--ctorigdstport. The counter keyword adds a counter to the rule.
Where do you put it? nft add rule appends at the end of the chain,
therefore after the counter drop. The -a option of nft list displays the
handle of each rule, its identifier in the chain.
sudo nft add rule inet c39_hote forward ip daddr 172.31.10.2 tcp dport 80 ct original proto-dst 8070 counter acceptsonde "partenaire -> hote:8070" docker exec c39-m-partenaire wget -q -T 3 -O - "http://$HOTE:8070/"sudo nft -a list chain inet c39_hote forwardpartenaire -> hote:8070 rc=1 wget: download timed outtable inet c39_hote { chain forward { # handle 1 type filter hook forward priority filter + 10; policy drop; ct state established,related accept # handle 2 counter packets 11 bytes 660 drop # handle 3 ip daddr 172.31.10.2 tcp dport 80 ct original proto-dst 8070 counter packets 0 bytes 0 accept # handle 4 }}The flow stays cut and the targeted rule (handle 4) counts 0 packets: it did
not see the packet, not because its criteria are wrong, but because the counter drop (handle 3), placed before it, has already decided. Its counter (11 packets) confirms it. The order of rules matters as much as their content.
nft insert rule … position <handle> inserts before the targeted rule. The
following command deletes the rule by its handle (read in the listing), then
reinserts it before the counter drop, whose handle it also reads.
H=$(sudo nft -a list chain inet c39_hote forward | awk '/proto-dst 8070/{print $NF}')sudo nft delete rule inet c39_hote forward handle "$H"sudo nft insert rule inet c39_hote forward position "$(sudo nft -a list chain inet c39_hote forward | awk '/counter packets .* drop/{print $NF}')" ip daddr 172.31.10.2 tcp dport 80 ct original proto-dst 8070 counter acceptsudo nft -a list chain inet c39_hote forwardsonde "partenaire -> hote:8070" docker exec c39-m-partenaire wget -q -T 3 -O - "http://$HOTE:8070/"sonde "partenaire -> internet" docker exec c39-m-partenaire wget -q -T 5 -O /dev/null http://deb.debian.org/debian/sudo nft list chain inet c39_hote forward | grep countertable inet c39_hote { chain forward { # handle 1 type filter hook forward priority filter + 10; policy drop; ct state established,related accept # handle 2 ip daddr 172.31.10.2 tcp dport 80 ct original proto-dst 8070 counter packets 0 bytes 0 accept # handle 5 counter packets 11 bytes 660 drop # handle 3 }}partenaire -> hote:8070 rc=0 api-c39partenaire -> internet rc=1 wget: download timed out ip daddr 172.31.10.2 tcp dport 80 ct original proto-dst 8070 counter packets 1 bytes 60 accept counter packets 16 bytes 960 dropThe rule (handle 5) is now before the refusal. The partner reaches the API
(positive test), and the rule's counter went from zero to 1 packet, the first of
the connection: the following ones fall under the established,related rule. So
it is this rule that restored the flow.
The negative test counts just as much: the partner still does not reach the
internet, and the refusal's counter went from 11 to 16 packets, which indicates
that this neighbouring flow stays closed. It proves something because this probe
had a baseline: it succeeded before the table was set up (rc=0 in the baseline
probes) and it succeeds again after its removal. Without this baseline, a
failure proves nothing, and with a firewall disabled for the test, the probe
would no longer say whether the rest stayed closed.
You then delete the test table, and the probe toward the internet confirms that the flow is restored.
sudo nft delete table inet c39_hote; echo "delete_rc=$?"rm -f c39-hote.nftsonde "partenaire -> internet" docker exec c39-m-partenaire wget -q -T 5 -O /dev/null http://deb.debian.org/debian/sudo nft list tablesdelete_rc=0partenaire -> internet rc=0table ip nattable ip filtertable ip6 nattable ip6 filtertable ip rawThat leaves the idea ruled out above to measure: an ACCEPT in DOCKER-USER,
facing a drop from another table. This complementary check rebuilds, in
miniature, the topology and the table of the demonstration, under the same
names: it therefore cannot be played on top of those objects. First remove the
topology, then play the next three blocks, which end with their own removal.
docker rm -f c39-m-api c39-m-voisin c39-m-partenaire c39-m-intrus >/dev/nulldocker network rm c39-m-front c39-m-partenaire c39-m-intrus >/dev/nullThe next block recreates two networks and two containers, then loads the same host table, with its drop policy. It displays nothing.
docker network create --subnet 172.31.10.0/24 c39-m-front >/dev/nulldocker network create --subnet 172.31.20.0/24 c39-m-partenaire >/dev/nulldocker run -d --name c39-m-api --network c39-m-front -p 8070:80 "$ALP" sh -c "$SRV" >/dev/nulldocker run -d --name c39-m-partenaire --network c39-m-partenaire "$ALP" sleep 600 >/dev/nullsleep 1cat > c39-hote.nft <<'EOF'table inet c39_hote { chain forward { type filter hook forward priority filter + 10; policy drop; ct state established,related accept counter drop }}EOFsudo nft -f c39-hote.nftThe ACCEPT rule below targets the flow of original port 8070, with no
restriction on the source: it is a trial. Four commands follow. The first
inserts it, the second probes the API from the partner, the last two read the
rule's counter (sed -n 3p keeps the rule's line) and that of the host's
counter drop.
sudo iptables -I DOCKER-USER -p tcp -m conntrack --ctorigdstport 8070 --ctdir ORIGINAL -j ACCEPTsonde "partenaire -> hote:8070" docker exec c39-m-partenaire wget -q -T 3 -O - "http://$HOTE:8070/"sudo iptables -L DOCKER-USER -n -v | sed -n 3psudo nft list chain inet c39_hote forward | grep counterpartenaire -> hote:8070 rc=1 wget: download timed out 3 180 ACCEPT tcp -- * * 0.0.0.0/0 0.0.0.0/0 ctorigdstport 8070 ctdir ORIGINAL counter packets 3 bytes 180 dropRead the two counters together. The DOCKER-USER ACCEPT saw 3 packets (180
bytes) and accepted them: the rule works. The host table's counter drop also
counts 3 packets (180 bytes), and the partner fails (rc=1). The
DOCKER-USER acceptance does not stop the other base chains of the FORWARD
hook: the host's table then judges the traffic and refuses it. Fixing on
Docker's side therefore changes nothing, and the refusal's counter tells where
the flow stops.
The last block removes the rule, the table, the file, the two containers and the
two networks. It displays the empty DOCKER-USER chain, then the number of
tables whose name contains c39.
sudo iptables -D DOCKER-USER -p tcp -m conntrack --ctorigdstport 8070 --ctdir ORIGINAL -j ACCEPTsudo nft delete table inet c39_hoterm -f c39-hote.nftdocker rm -f c39-m-api c39-m-partenaire >/dev/nulldocker network rm c39-m-front c39-m-partenaire >/dev/nullsudo iptables -S DOCKER-USER; sudo nft list tables | grep -c c39 || true-N DOCKER-USER0Why does a packet sent straight to the container leave DOCKER-USER at zero?
A counter at zero in DOCKER-USER does not always prove that the rule is badly
written: the packet may have been dropped before reaching FORWARD. Docker
indeed maintains an ip raw table, whose PREROUTING chain is evaluated before
connection tracking (priority raw). The following command reads it before any
container, then after the publication of a port. The block creates two objects
under the same names as the demonstration, which is already removed at this
stage, and ends with their removal.
sudo nft list table ip rawdocker network create --subnet 172.31.10.0/24 c39-m-front >/dev/nulldocker run -d --name c39-m-api --network c39-m-front -p 8070:80 "$ALP" sleep 300 >/dev/nullsudo nft list table ip rawdocker rm -f c39-m-api >/dev/nulldocker network rm c39-m-front >/dev/nulltable ip raw { chain PREROUTING { type filter hook prerouting priority raw; policy accept; }}table ip raw { chain PREROUTING { type filter hook prerouting priority raw; policy accept; ip daddr 172.31.10.2 iifname != "br-9a32a59791d5" counter packets 0 bytes 0 drop }}Before any container, the chain is empty. With a container, Docker adds a rule
that drops any packet destined for the container's address (172.31.10.2) that
does not arrive through its network's bridge (br-…, whose name changes with
each network). On the measurement VM, a container with no published port got one
too. A client that targets the container's address directly, without going
through the bridge, is therefore refused at the prerouting hook. Measured with
the partner container, on another network, targeting 172.31.10.2 instead of
the published port: the request times out, this rule's counter goes to 3 packets
and DOCKER-USER, empty, saw nothing. To diagnose such a flow, read the counter
of the ip raw table rule.
Do these rules survive a reboot?
No. Rules set with iptables -I and with nft add or nft insert live in
memory: they disappear when the machine reboots. This is handy for a trial, and
insufficient for a lasting fix. To write a rule that persists, see the guide
Configure a firewall with nftables and, to
choose the tool, Linux firewalls: understand before you
configure.
How do you roll back in an emergency?
If a probe hangs or if you lose internet access from a container, remove
everything the lesson set up: the two DOCKER-USER rules (the one from the
section on the published port and the ACCEPT of the complementary check), the
host's table and its file, the topology, then the objects of the MTU
measurement.
sudo iptables -D DOCKER-USER -s 172.31.30.0/24 -p tcp -m conntrack --ctorigdstport 8070 --ctdir ORIGINAL -j DROPsudo iptables -D DOCKER-USER -p tcp -m conntrack --ctorigdstport 8070 --ctdir ORIGINAL -j ACCEPTsudo nft delete table inet c39_hoterm -f c39-hote.nftdocker rm -f c39-m-api c39-m-voisin c39-m-partenaire c39-m-intrus >/dev/nulldocker network rm c39-m-front c39-m-partenaire c39-m-intrus >/dev/nulldocker rm -f c39-m-a c39-m-b >/dev/nulldocker network rm c39-m-std c39-m-reduit >/dev/nullA command that targets an object already removed answers with an error (rule, table, container or network not found) with no consequence: move on to the next one. These rules do not survive a reboot, but waiting for a reboot to erase them leaves the failure in place until then. The table with a drop policy cuts the host's routed traffic that its rules do not accept, as long as it is in place: the measurement showed it for internet access from a container.
How do you spot an MTU problem?
The MTU (Maximum Transmission Unit) is the maximum size of a packet that an interface agrees to send. Each hop has its own: the host's interface, the Docker network's bridge, the container's interface. The mismatch is a problem in one precise direction: when a container's MTU is larger than that of a hop on the path and ICMP is filtered, path MTU discovery (PMTUD) stops working. The typical symptom is a connection that is established, then large transfers that freeze. The guide on MTU, MSS and PMTUD (in French) details this mechanism.
The demonstration does not reproduce this symptom: it teaches you to read the
MTU at each hop and to probe it. The com.docker.network.driver.mtu option sets
the MTU of a Docker network: you create one at 1400 for the measurement, next to
a standard network. The topology of the previous sections is already removed:
the complementary check ended with its removal. The next two commands check it.
docker ps -aq --filter name=c39-m- | wc -lsudo nft list tables0table ip nattable ip filtertable ip6 nattable ip6 filtertable ip rawNo container remains, and the tables are those of the initial state. The next
command computes the host's interface (IFACE, the one of the default route),
reads its MTU, creates the two networks and two containers, then reads the MTU
of their eth0 interface.
IFACE=$(ip -4 route show default | awk '{print $5}' | head -1); echo "IFACE=$IFACE"ip -o link show "$IFACE" | grep -o 'mtu [0-9]*'docker network create --subnet 172.31.40.0/24 c39-m-std >/dev/nulldocker network create --subnet 172.31.50.0/24 -o com.docker.network.driver.mtu=1400 c39-m-reduit >/dev/nulldocker run -d --name c39-m-a --network c39-m-std "$ALP" sleep 300 >/dev/nulldocker run -d --name c39-m-b --network c39-m-reduit "$ALP" sleep 300 >/dev/nullfor c in c39-m-a c39-m-b; do printf '%s eth0 : ' "$c"; docker exec "$c" ip -o link show eth0 | grep -o 'mtu [0-9]*'; doneIFACE=enp1s0mtu 1500c39-m-a eth0 : mtu 1500c39-m-b eth0 : mtu 1400Read the MTU at each hop: the host's interface is at 1500, the container of
the standard network too, and the one on the c39-m-reduit network (reduit is
French for reduced) at 1400, the option's value. A mismatch between two hops of
the same path is the first clue. To confirm it, you send from the host a ping
whose DF bit (Don't Fragment) is set by -M do: the packet must not be
fragmented, so it fails if it exceeds a hop's MTU. With -s, you set the size
of the data; the IP header and the ICMP header add 28 bytes, so 1472 bytes of
data make a 1500-byte packet. This ping is the iputils one, installed on the
host: BusyBox's, in the Alpine image, has no -M option.
ping -c1 -W2 -M do -s 1472 172.31.40.2 | grep -E 'bytes from|transmitted'ping -c1 -W2 -M do -s 1472 172.31.50.2 2>&1 | grep -E 'too long|transmitted'ping -c1 -W2 -M do -s 1372 172.31.50.2 | grep -E 'bytes from|transmitted'1480 bytes from 172.31.40.2: icmp_seq=1 ttl=64 time=0.047 ms1 packets transmitted, 1 received, 0% packet loss, time 0msping: sendmsg: Message too long1 packets transmitted, 0 received, +1 errors, 100% packet loss, time 0ms1380 bytes from 172.31.50.2: icmp_seq=1 ttl=64 time=0.043 ms1 packets transmitted, 1 received, 0% packet loss, time 0msThe 1500 network lets the 1500-byte packet through. The 1400 network refuses the
same packet with Message too long, and accepts a 1400-byte packet (1372 of
data). The size displayed by ping, 1480, counts the data and the 8 bytes of
the ICMP header, without the IP header. By looking for the largest size that
gets through, you obtain the path's effective MTU. This measurement probes the
path between the host and the container, through the bridge. A tunnel or a VPN
located further away is probed in the same way, with a target beyond the tunnel,
but this lesson did not measure it. The guide on
ICMP (in French), the protocol that carries
ping, details this notion.
The cleanup removes the two containers and the two networks of this section.
docker rm -f c39-m-a c39-m-b >/dev/nulldocker network rm c39-m-std c39-m-reduit >/dev/nulldocker network ls --format '{{.Name}}' | grep -c '^c39-m-' || true0Troubleshooting
Each row links a symptom you observe to its probable cause, to the check that confirms it and to the most targeted fix. When a symptom matches no row, go back to the method: one probe per hop, one counter per rule.
| Symptom | Cause | Check | Fix |
|---|---|---|---|
A DOCKER-USER rule on --dport of a published port blocks nothing | The DNAT has already replaced the port: the chain sees the container's port | Rule counter at 0 0 after a test | Filter with -m conntrack --ctorigdstport and replay the probes |
| The host reaches the published port, a remote client does not | Another nftables table, with a drop policy on the forward hook, refuses the routed traffic | sudo nft list tables, then sudo nft list chain for each unknown table | Add a targeted rule in that table, then test a neighbouring flow that must stay closed |
An nft add rule is in place, its counter stays at zero and the flow is cut | A refusal placed before it in the chain has already decided | sudo nft -a list chain: the order and the handles | sudo nft insert rule … position <handle> before the refusal rule |
A packet to the container's address is refused and the DOCKER-USER counters stay at zero | Docker drops, at the prerouting hook, in the ip raw table, the packets destined for the container that do not arrive through its bridge | sudo nft list table ip raw: the drop rule with iifname != and its counter | Go through the published port or through the container's network, not through its address from outside the bridge |
ACCEPT in DOCKER-USER has no effect | A base chain of another table also decides | The client fails despite the ACCEPT, and sudo nft list tables shows another table | Fix in the table that refuses, not in DOCKER-USER |
| A container name does not resolve | The client is on a different network than the target | nslookup from a container on the same network, then from the other | Use the host's address and the published port, or join the same network |
| The connection is established, but large transfers freeze | The container's MTU is larger than that of a hop on the path, and filtered ICMP prevents discovery | ip -o link show at each hop, then ping -M do | Align the network's MTU with com.docker.network.driver.mtu |
failed to create endpoint […] on network bridge: adding interface […] to bridge docker0 failed: Device does not exist | The bridge module was removed, for example by modprobe -r br_netfilter, which also removes its unused dependencies: docker0 has disappeared | The message cites docker0 | sudo systemctl restart docker, which recreates docker0 |
The last row is not about the firewall. It appears when a kernel module is
unloaded by hand during trials: modprobe -r br_netfilter, the module that
subjects bridge traffic to netfilter rules, also removed the bridge module, on
which docker0 depended. The default bridge network stayed broken until
Docker was restarted.
Put it into practice
The lab has you repair a routed flow in the network namespace of a router container: a rule of its internal firewall blocks the business flow, and you locate it with probes at each hop before concluding to a routing or service failure. You fix only this flow, keeping the exclusions that must stay in place. The tests measure the real state: the service's answer arrives, the negative probes still fail and make the refusal counters go up, and the result holds when the whole is recreated from its declaration. Removing the whole firewall makes these tests fail.
A hint for the location: the tables of a container that has NET_ADMIN live in
its own network namespace, so sudo nft list tables on the host does not show
them, whereas docker exec <container> nft list ruleset reads them.
Key points
You locate the faulty hop with probes and counters, you fix one rule, and you prove it with positive and negative tests.
- You know that a packet to a published port is rewritten by the DNAT, then
crosses
FORWARD:DOCKER-USERfirst,DOCKER-FORWARDnext, then the host's other nftables tables, whose priority is higher thanfilter. - You know that a test from the host to
127.0.0.1goes throughdocker-proxy, does not crossFORWARDand does not prove that a remote client gets through. - You read
docker infofor the firewall backend andsudo nft list tablesfor all the tables, not only Docker's. - You probe a flow hop by hop: a name resolves only on the network shared with
the target, and the MTU is read at each hop with
ping -M do. - You read a rule's counter: at zero after a test, it did not see the packet, because its criteria do not match or because a decision was made before it.
- You filter a published port with
--ctorigdstport, because the chain sees the destination after DNAT. - You know that an
ACCEPTinDOCKER-USERdoes not cancel another table'sdrop, that annftrule is placed withinsert … positionbefore the refusal, and that these rules do not survive a reboot. - You never disable the firewall to test: a negative test that still fails, with a baseline measured before, shows that the rest stayed closed.
Knowledge check
Check that you can predict what a rule sees, locate the firewall that refuses and prove a fix.
Knowledge check
Check what you have learned with this interactive quiz
How it works
- The timer starts when you click Start
- Multiple choice, true/false and short answer questions
- You can move between questions
- Detailed results are shown at the end
Starts the quiz and the timer
Review
(0/0)Score by domain
A domain groups several guides and gets several questions, so its score is more reliable than a per-topic score, which often rests on a single question.
Summary
Strengths
No topic passed at 80% on at least two questions yet.
Weak areas
No topic below the pass mark.
Recommended next
Hints before you try again?
Continue the course: Find orphan Docker volumes without deleting everything
A new full quiz with random questions
Work again only on the questions you missed