When kubectl answers connection refused while it targets the right cluster, look for the failure in the control plane, and it is diagnosed on the node, not from your workstation. On a cluster deployed with kubeadm, the API server, the scheduler and the controller-manager are static Pods: the kubelet starts them from YAML files, and one faulty file is enough to stop them. This lesson teaches you to read these failures with crictl and journalctl, to fix the faulty manifest, and then to place a static Pod yourself to understand the mechanics. It is aimed at people who operate a kubeadm cluster or prepare for the CKA, whose Troubleshooting domain weighs 30% in the official CNCF curriculum (CKA v1.37 version).
Two other pages cover what this lesson leaves aside. Debugging applications takes over as soon as the cluster is healthy and it is a Pod or a Service that misbehaves. The incident diagnosis method (in French) tells you which of the two cases you are in, before you open either one.
What you will learn
- Say that the API server, the scheduler and the controller-manager of a kubeadm cluster are static Pods, read from
/etc/kubernetes/manifests - Diagnose an unreachable API without
kubectl, withcrictlandjournalctl -u kubelet - Fix a faulty flag in the API server manifest without disabling authorization
- Place a static Pod on a worker and find it again as a mirror Pod
- Say why deleting a mirror Pod deletes nothing
Prerequisites
- A kubeadm cluster with SSH access to the nodes themselves, control plane and workers, and
sudorights on them - The notions from the architecture of a Kubernetes cluster, the control plane and the worker nodes
- The first reflexes for reading the state of a cluster (in French)
Commands run on a node (crictl, reading and editing /etc/kubernetes/manifests, journalctl) run as root, so with sudo or from a root shell.
Without SSH access to a cluster, a kind cluster is enough to read the manifests and the logs: its nodes are kubeadm nodes, with /etc/kubernetes/manifests/, crictl and the kubelet journal. Replace ssh <node> with docker exec <node-name>. The labs of this lesson, however, run on virtual machines, as in the certification exam: you connect over SSH to real machines, where the kubelet runs as a systemd service on the host. On kind, the kubelet runs inside the node container, and breaking or restarting it does not reproduce what you will do on a VM.
Where do you start with a failing cluster?
Start with the broadest question, does kubectl answer?, and work down to the most precise one, stopping as soon as a step returns an anomaly. The general approach in four levels (cluster, node, Pod, network) is the one from the incident diagnosis method (in French), already covered: this lesson details its first level, the one where kubectl itself is down.
A shortcut saves time. If the symptom points to a single worker, go straight to the lesson Troubleshoot a node: kubelet and NotReady. If on the contrary kubectl no longer answers, first check that it targets the right cluster: kubectl config current-context gives the active context, and the error message cites the address it tried to reach. An address of localhost:8080 means kubectl found no kubeconfig, which happens with a sudo kubectl run on the node without KUBECONFIG. That is not a cluster failure. If the context and the address are the right ones, no diagnosis is possible from your workstation: connect to the control plane node. The kubelet and the container runtime can still be queried there, even when the API server is down.
Which tools do you use when kubectl no longer answers?
Two tools replace kubectl on the node: crictl to see the containers, and journalctl to read what the kubelet says. The commands below run over SSH on the node.
systemctl status kubelet # is the kubelet service holding up?sudo journalctl -u kubelet --no-pager --since "10 min ago" | tail -50sudo crictl ps -a # containers, alive or deadsudo crictl pods # Pods as seen by the runtimess -tlnp | grep -E '6443|2379|10250|10259|10257' # listening portscrictl talks directly to the container runtime (containerd). It therefore sees the containers even when the API is down, and it reads the logs of stopped containers as long as the kubelet has not cleaned them up. It is not installed everywhere: failing that, read journalctl -u kubelet, or query containerd with ctr.
The following table lists the component ports. Look at the "Listens on" column, it explains many failed diagnoses: port 10257 of the controller-manager and port 10259 of the scheduler are only reachable from the node itself. Probing 10259 from your workstation therefore proves nothing.
| Port | Component | Listens on | Role |
|---|---|---|---|
| 6443 | kube-apiserver | all interfaces | Main entry point of the API |
| 2379 | etcd (client) | loopback and node IP | Reading and writing the state |
| 2380 | etcd (peer) | node IP | Replication between members |
| 10250 | kubelet | all interfaces | Kubelet API (metrics, exec) |
| 10256 | kube-proxy | all interfaces | Health check |
| 10257 | kube-controller-manager | loopback only | Health check |
| 10259 | kube-scheduler | loopback only | Health check |
Default ports of a kubeadm control plane node in 1.37. The health ports of the controller-manager and the scheduler stay local on purpose: it is the kubelet, local as well, that queries their probes.
What are the control plane static Pods?
A static Pod is a Pod that the kubelet creates by itself, from a YAML file placed on the node, without going through the API server. This is what allows the control plane to start: the API server cannot be launched by a Deployment, since the Deployment needs the API server.
On a kubeadm node, the kubelet watches a directory designated by the staticPodPath field of its configuration, /etc/kubernetes/manifests by default. This directory holds the four control plane files: etcd.yaml, kube-apiserver.yaml, kube-controller-manager.yaml and kube-scheduler.yaml. The containers of these Pods can be seen with crictl, on the control plane node.
sudo crictl ps -a | head -12CONTAINER IMAGE CREATED STATE NAME ATTEMPT POD ID POD NAMESPACE1be701d39678c 2db038c9db509 24 minutes ago Running kube-controller-manager 3 127fb66bf9edc kube-controller-manager-k8s-cp.lab kube-system14cf537ca88e5 20824b0c11f7d 24 minutes ago Running kube-scheduler 3 b8c0797a16d26 kube-scheduler-k8s-cp.lab kube-system57740d9210b31 7a918dfe48696 24 minutes ago Running kube-apiserver 0 7d12525b032a4 kube-apiserver-k8s-cp.lab kube-system6b95321d34b2d 20824b0c11f7d 25 minutes ago Exited kube-scheduler 2 b8c0797a16d26 kube-scheduler-k8s-cp.lab kube-system[...]Look at the POD column: each control plane Pod carries the name of the component followed by the name of the node (-k8s-cp.lab), which marks a static Pod. Also look at STATE and ATTEMPT: an Exited container next to a Running container of the same name, with a higher ATTEMPT, shows that the kubelet restarted the component.
The kubelet rereads the directory continuously. An added file starts the Pod, a modified file recreates it, a removed file stops it. A faulty manifest therefore prevents its component from starting, and fixing the file is enough to restart it, with no restart command.
The following diagram follows the path of a manifest: the file placed in staticPodPath is reread by the kubelet, which has containerd run it, then publishes a mirror Pod in the API server. Look at the direction of the arrows: the file commands, the mirror only reflects.
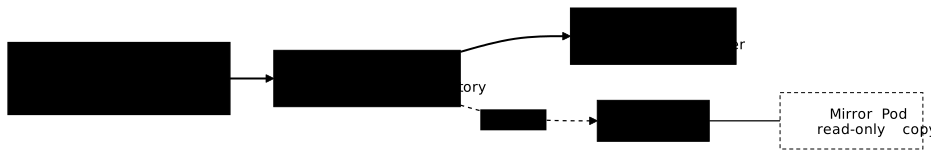
The kubelet also publishes, in the API, a read-only copy of each static Pod: the mirror Pod. This is what you see in kubectl get pods -n kube-system, under the Pod name suffixed with the node name, for example kube-apiserver-k8s-cp.lab. The mirror is there to observe, not to drive: the file remains the only source of truth.
How do you diagnose a component that will not start?
For any control plane component, the approach is the same: first check whether its container exists, read why it stopped, then fix the file.
- Look for the container with
sudo crictl ps -a | grep <component>: is itRunning,Exited, or absent? - Read the last error of the container with
sudo crictl logs <identifier>. - If the container does not even exist, read the kubelet journal with
sudo journalctl -u kubelet | grep <component>: it says whether it refuses the manifest. - Open the manifest in
/etc/kubernetes/manifests/and compare it with a healthy manifest, for example the one from another control plane node or the documentation. - Fix the file: the kubelet recreates the Pod with no other command.
- Check with
sudo crictl ps | grep <component>, thenkubectl get pods -n kube-systemas soon as the API answers.
The two situations are not read in the same place. If the container exists and has stopped, the component started and then exited on an error, and crictl logs holds it. If the container does not exist, the kubelet could not create the Pod, and its journal explains why.
Why does the API server no longer answer?
This is the most visible failure: without an API server, kubectl is useless. The symptom is The connection to the server ... was refused or a timeout, and the other components write connection errors in their logs.
Take a failure you can reproduce on a test cluster: an API server manifest that points to the wrong etcd port, 2399 instead of 2379. Before changing a manifest, keep a copy of it outside the watched directory: a backup file left in /etc/kubernetes/manifests would be read as a manifest. On the control plane node, copy the manifest and change the port, then wait 90 seconds for the kubelet to restart the API server:
sudo cp /etc/kubernetes/manifests/kube-apiserver.yaml /root/kube-apiserver.yaml.sauvesudo sed -i 's|--etcd-servers=https://127.0.0.1:2379|--etcd-servers=https://127.0.0.1:2399|' /etc/kubernetes/manifests/kube-apiserver.yamlFrom this moment, the API is no longer ready to serve. Reread the flag in the manifest, then look for the API server container:
sudo grep -- --etcd-servers /etc/kubernetes/manifests/kube-apiserver.yamlsudo crictl ps -a | grep apiserver - --etcd-servers=https://127.0.0.1:23990052568404d11 7a918dfe48696 2 seconds ago Running kube-apiserver 2 c12352735f6a7 kube-apiserver-k8s-cp.lab kube-system723fb8f10e513 7a918dfe48696 33 seconds ago Exited kube-apiserver 1 c12352735f6a7 kube-apiserver-k8s-cp.lab kube-systemLook at the STATE and ATTEMPT columns: an Exited container at ATTEMPT 1, and a new container at ATTEMPT 2, created 2 seconds earlier. The kubelet restarts the API server in a loop, so the error is in the container, not in the kubelet. The most recent container shows Running for a few seconds before stopping in turn: do not conclude the failure is resolved from the STATE column alone. Read the container journal, with its identifier:
sudo crictl logs 0052568404d11 2>&1 | tail -15[...]W1110 22:37:13.855754 1 logging.go:55] [core] [Channel #1 SubChannel #3] grpc: addrConn.createTransport failed to connect to {Addr: "127.0.0.1:2399", ServerName: "127.0.0.1:2399", }. Err: connection error: desc = "transport: Error while dialing: dial tcp 127.0.0.1:2399: connect: connection refused"[...]The W line names the refused address, 127.0.0.1:2399 (dial tcp 127.0.0.1:2399: connect: connection refused). The API server program is not at fault: it is its --etcd-servers flag that points to a port where etcd does not listen, while it listens on 2379. Put the original value back, here by restoring the copy made above:
sudo cp /root/kube-apiserver.yaml.sauve /etc/kubernetes/manifests/kube-apiserver.yamlThe kubelet recreates the Pod, and the API is ready about 25 seconds after the restoration. Check with the health probe rather than the mere presence of the container:
kubectl get --raw /readyzokA Running container does not prove the API is healthy: /readyz answers ok only when the API is ready to serve, etcd included. The older /healthz, deprecated since Kubernetes 1.16, also answers ok: you will come across both.
The error message changes with the nature of the fault. The following table links the common faults to what you read, and to where to read it:
| Fault in the manifest | What you read | Where |
|---|---|---|
| Flag the API server does not know | the container exits in less than a second; its log is one line, Error: unknown flag: --authorization-modes | crictl logs on the container with the most recent POD ID, right away: the kubelet removes dead containers quickly |
| Wrong flag value (port, address) | connection refused or no such host towards that value | crictl logs |
| Nonexistent certificate path | open /etc/kubernetes/pki/...: no such file or directory | crictl logs |
| Invalid YAML (indentation, quote) | no container, a file reading error | journalctl -u kubelet |
| Port already in use | bind: address already in use | crictl logs |
| etcd unreachable | connection refused towards :2379 | crictl logs |
In the last row, etcd itself is unreachable: the problem is in etcd, not in the API server. The lesson etcd covers the health and repair of the database. An expired certificate is spotted by a message that contains certificate has expired in the same logs. Its diagnosis and renewal belong to the "Renewing certificates" section of the kubeadm guide.
A rule about fixing: repairing means recovering the expected behavior without weakening another one. When the API server does not start, the temptation is to remove a security flag or give it a permissive value. The API then restarts, but it accepts everyone. After a repair, reread the manifest: --authorization-mode=Node,RBAC must still be there.
Why do new Pods stay Pending with no event?
Without a scheduler, new Pods stay Pending: no component assigns them a node. Pods that are already running are not affected. The distinctive sign is the absence of any scheduler event in kubectl describe pod: neither Scheduled nor FailedScheduling. A Pod that is Pending for lack of resources, on the other hand, shows a FailedScheduling event.
kubectl get pods -n kube-system -l component=kube-schedulerkubectl logs -n kube-system kube-scheduler-k8s-cp.labIf kubectl does not answer, or if the scheduler Pod is missing, move to the node with crictl ps -a | grep scheduler, then crictl logs. In the manifest /etc/kubernetes/manifests/kube-scheduler.yaml, check three points: the --kubeconfig=/etc/kubernetes/scheduler.conf flag, the registry.k8s.io/kube-scheduler image at the cluster version, and port 10259. After the fix, the kubelet recreates the Pod, and the Pending Pods are placed.
Why do Deployments no longer progress?
Without kube-controller-manager, many control loops stop converging: replication, Jobs, the node lifecycle, service accounts, garbage collection. The symptoms show on the workload side: a ReplicaSet no longer creates Pods, a Deployment does not move forward.
The controller-manager also hosts the controller that watches node health. Without it, a node that is really unreachable is no longer marked NotReady and its Pods are not evicted, which is misleading: the cluster looks healthy while a controller is dead. The reading is the same as for the other components.
kubectl get pods -n kube-system -l component=kube-controller-managersudo crictl ps -a --name kube-controller -q | head -1 # container identifiersudo crictl logs <identifier>In /etc/kubernetes/manifests/kube-controller-manager.yaml, the flags that point to files are the most fragile: --kubeconfig, --root-ca-file, --cluster-signing-cert-file, --cluster-signing-key-file and --service-account-private-key-file, all under /etc/kubernetes/. A wrong path shows up in crictl logs as no such file or directory.
How do you place a static Pod and find it as a mirror Pod?
To understand a static Pod, place one. You write it on a worker, in the directory designated by the kubelet configuration, and you find it in the API under its mirror name. The path cannot be guessed, it is read: on the worker, open /var/lib/kubelet/config.yaml and note staticPodPath.
ssh k8s-w1.labsudo grep staticPodPath /var/lib/kubelet/config.yamlstaticPodPath: /etc/kubernetes/manifestsThen drop a Pod manifest in this directory. Here is a minimal Pod that only sleeps, with a pinned image:
printf '%s\n' 'apiVersion: v1' 'kind: Pod' 'metadata:' ' name: diag-statique' ' namespace: default' 'spec:' ' containers:' ' - name: c' ' image: busybox:1.38.0@sha256:a46257e06c82ad85242d0d38077d0a52d9896389ca60a1a59d3463db586e5fa4' ' command: ["sleep", "3600"]' | sudo tee /etc/kubernetes/manifests/diag-statique.yamlapiVersion: v1kind: Podmetadata: name: diag-statique namespace: defaultspec: containers: - name: c image: busybox:1.38.0@sha256:a46257e06c82ad85242d0d38077d0a52d9896389ca60a1a59d3463db586e5fa4 command: ["sleep", "3600"]The kubelet reads the file and publishes the mirror Pod in the API. From the control plane:
kubectl get pod diag-statique-k8s-w1.lab -o wideNAME READY STATUS RESTARTS AGE IP NODE NOMINATED NODE READINESS GATESdiag-statique-k8s-w1.lab 1/1 Running 0 1s 10.244.38.107 k8s-w1.lab <none> <none>Look at the Pod name: diag-statique followed by -k8s-w1.lab, the node name. This suffix is the signature of a static Pod. On the lab cluster, where the image was already on the node, the mirror was Running one second after the file was written. But it remains a reflection: to know whether the c container really runs, look on the worker with sudo crictl ps. The mirror Pod also carries annotations that say where it comes from:
kubectl get pod diag-statique-k8s-w1.lab -o jsonpath='{.metadata.annotations}'{"cni.projectcalico.org/containerID":"eaad9f76af23dae6ef3ef2ae98de4854a427f105a2585d8c41159292e899e35f","cni.projectcalico.org/podIP":"10.244.38.107/32","cni.projectcalico.org/podIPs":"10.244.38.107/32","kubernetes.io/config.hash":"69f56e1e9a2fdab5ac4cbc0792ffe6e2","kubernetes.io/config.mirror":"69f56e1e9a2fdab5ac4cbc0792ffe6e2","kubernetes.io/config.seen":"2026-11-13T14:54:50.723534534Z","kubernetes.io/config.source":"file"}The value "kubernetes.io/config.source":"file" confirms that this Pod comes from a file, not from the API. Now try to delete it with kubectl delete pod diag-statique-k8s-w1.lab: the command takes about a minute to return, then the mirror is recreated at once, with a new UID, because the kubelet rereads the file. It shows Pending for a few seconds, then Running. The container itself was never stopped: sudo crictl ps on the worker shows the same ID. A Pending read right after the delete is therefore not a failure. Deleting a mirror Pod deletes nothing. To stop a static Pod, remove its manifest from the watched directory, with sudo rm /etc/kubernetes/manifests/diag-statique.yaml.
A malformed manifest, for its part, appears nowhere in the API: there is neither a Pod nor a mirror. It is the kubelet journal, on the worker, that says what it objects to, with sudo journalctl -u kubelet | grep diag-statique.yaml, replacing the name with that of your manifest file.
Summary checklist
This checklist gathers the commands of the lesson, sorted by starting symptom. Keep it at hand during an incident.
To locate a failure at the cluster level, three commands run from your workstation as long as the API answers:
kubectl cluster-info # API reachable?kubectl get nodes -o wide # nodes Ready?kubectl get pods -n kube-system # components OK?As soon as kubectl no longer answers and its context is the right one, everything happens on the control plane node, with the runtime and the kubelet journal:
ssh <control-plane>sudo crictl ps -a | grep -E 'apiserver|scheduler|controller|etcd'sudo journalctl -u kubelet --since "5 min ago" | grep -i errorsudo cat /etc/kubernetes/manifests/<component>.yaml # flags, paths, YAMLFor a worker that goes NotReady, the approach lives in the lesson Troubleshoot a node: kubelet and NotReady. For etcd, health, quota and snapshot restoration are covered in the etcd lesson and the guide Back up and restore Kubernetes. DNS and Pod network failures are handled with CoreDNS and Pod networking.
Put it into practice
Two labs run on a real kubeadm cluster, a control plane (k8s-cp.lab) and a worker (k8s-w1.lab) in virtual machines. In the first, kubectl answers connection refused: a colleague says they "adjusted a flag" on the API server before leaving. You diagnose on the node, with crictl and journalctl -u kubelet, you fix the static manifest, then you check that kubectl get nodes and /readyz answer. The validation also rereads the manifest: the API server must still declare Node,RBAC, and removing the faulty line to make it start does not pass. Start it with dsoxlab start cka-troubleshoot-apiserver.
In the second, the network team wants a status page served by the worker itself, even when the API server is unreachable. On k8s-w1.lab you write the manifest of a static-web Pod (namespace default, label role: static, container web on port 80), in the directory designated by staticPodPath, then you find it in the API under its mirror name, static-web-k8s-w1.lab. The validation reads the file on the worker, the mirror Pod in the API, and asks the worker runtime whether it really runs the container. Start it with dsoxlab start cka-static-pod.
The full scenario, three independent failures with nobody to ask, is the capstone of the CKA exercises.
Key takeaways
- If
kubectldoes not answer, first check its context and the address it cites, then connect to the control plane node and usecrictlandjournalctl -u kubelet. - The API server, the scheduler, the controller-manager and etcd of a kubeadm cluster are static Pods, read from the directory designated by
staticPodPath, that is/etc/kubernetes/manifests. - The kubelet recreates a static Pod as soon as its file changes: fixing the manifest is enough, with no restart.
- An
Exitedcontainer is explained withcrictl logs, a missing container with the kubelet journal. - Repair the API server without weakening its authorization: the manifest keeps
--authorization-mode=Node,RBAC, and/readyzanswersok(the older/healthz, deprecated since Kubernetes 1.16, also answersok). - A mirror Pod is recognized by its
-<node name>suffix and by thekubernetes.io/config.source: fileannotation. Deleting it deletes nothing. - To stop a static Pod, remove its file from the watched directory.
Test your knowledge
Seven questions on what separates a quick diagnosis from half an hour lost: where the control plane manifests live, which tool reads a dead container, and which port is probed from where.
Knowledge check
Check what you have learned with this interactive quiz
How it works
- The timer starts when you click Start
- Multiple choice, true/false and short answer questions
- You can move between questions
- Detailed results are shown at the end
Starts the quiz and the timer
Review
(0/0)Score by domain
A domain groups several guides and gets several questions, so its score is more reliable than a per-topic score, which often rests on a single question.
Summary
Strengths
No topic passed at 80% on at least two questions yet.
Weak areas
No topic below the pass mark.
Recommended next
Hints before you try again?
Continue the course: Troubleshoot a Kubernetes node: kubelet and NotReady
A new full quiz with random questions
Work again only on the questions you missed