Publishing a web service does not mean starting a process: it means making a function that specific users expect reliably accessible. This lesson opens the "Publish a web service" training: before talking about DNS names, ports or a reverse proxy (an intermediate server that receives requests in place of the application, then forwards them to it), you need to be able to name precisely what you are publishing. You will learn to tell a running process from a service that answers, a full application from a simple static site, and to write the minimal contract a service must honour once published.
What you will learn
- Tell service, application, process, socket, static site and API apart, and know which of these notions answers which question
- Describe the users, dependencies, data and requirements of a service before publishing it
- Observe a service with
ss -ltnp,psandcurl -w, then record what you saw in a service sheet - Explain why a started process, or even a container in the
runningstate, does not prove that a service delivers what is expected of it
Prerequisites
This lesson assumes you can read an IP address and a port, use a terminal, and recognise at a glance a DNS resolution and an HTTP request, without yet being able to explain them in detail: that is the subject of the next two lessons of this foundation. If these notions are new to you, the guides IP and subnets (in French), TCP vs UDP (in French), DNS (in French) and HTTP and HTTPS (in French) give the reading basics you need. No particular tool or reverse proxy is required here: this training stays independent of the product that will expose your services when they are actually published.
What are a client, a server, a request and a response?
A client sends a request, a server returns a response: the rest of this
training is only a variation on those four words. The client (a browser,
curl, another application) opens a network connection and makes a
request: "give me this", "save that". The server listens on that
connection, handles the demand and returns a response, which usually
contains a resource (a page, a record, a computation result) in a given
representation (HTML, JSON, an image). The same resource can have several
representations: a product page exists as HTML for a browser and as JSON for a
mobile application, without the underlying data changing.
This vocabulary looks elementary, but it serves as a constant reference: in the following lessons, a misunderstood request, a misread response or a confusion between the resource and its representation explain most failed diagnoses.
How do service, application, process, socket, static site and API differ?
Six words often used interchangeably actually name six distinct notions: confusing a process with a service, or a static site with an API, is a frequent cause of a publication that is poorly understood. The table fixes a precise vocabulary for the rest of the foundation.
| Term | What it means |
|---|---|
| Process | A program running on a machine, identified by a unique number, the PID |
| Socket | The network listening point a process opens (an address and a port) |
| Application | The code and its business logic: what decides what to answer |
| Service | What is delivered to the user reliably over time, not merely demonstrated once |
| Static site | Files (HTML, images, scripts) served as they are, with no computation specific to each request |
| API | An interface designed for a calling program, not for a human browser |
A process can very well be started, hold a socket, and still deliver no usable service: it waits for a missing configuration, for an unreachable database, or answers an error on every business call. That is why this foundation treats the service as the central notion: it alone makes a promise to a user, the other five describe only building blocks of that promise.
An API is not a separate type of server: it is an exchange contract (often in JSON, sometimes in XML) intended for a program, whereas a static site answers with pages that are already prepared. Many real services combine the two: a static site for the interface, an API behind it for the data, a single public name for both.
What changes between a development server and a production-ready service?
A development server and a production-ready service can run exactly the same code, but only the second promises something to a user you do not know personally. A development server starts with one command, shows its errors in plain view, reloads the code at every change, and stops without consequence when you close the terminal: that is intended, it serves you, while you write the code.
A production-ready service must survive your absence. It has a reproducible startup (not "launched once by hand and forgotten"), a configuration kept outside the code (addresses, quotas, logging mode), secrets that live neither in the code nor in the logs (passwords, API keys, tokens), and a state that must, or must not, survive a restart depending on whether it is business data to keep or a simple cache to rebuild. These four points, startup, configuration, secrets and state, are what a service sheet must describe before any publication: they cannot be guessed by reading the code once.
What is a publication contract?
Publishing a service means committing to a verifiable contract: who can access it, under which name, with what availability and what latency, and who answers for it when it breaks. This publication contract comes before any question of reverse proxy or tooling: it defines what the tool will have to hold, not how it will hold it.
Five elements make up this contract:
- the names by which the service is reached (one or several DNS names, sometimes a bare IP internally);
- the exposed URLs, that is, the paths that make sense to the user, to be told apart from the application's internal paths;
- the authorised access: public, restricted to an internal network, or behind authentication;
- the expected availability and latency, expressed in verifiable terms ("answers in under one second", "reachable 99% of the time"), not in vague wording;
- the operator, the person or team who answers when the service no longer keeps its promise.
A service without this written contract is not necessarily badly built, but it is impossible to verify: nobody can say whether it works "as planned", for lack of having written down what was planned.
Why doesn't a technical response prove that the service works?
A 200 response code and a container in the running state prove that a
process answers, never that the expected business function works. Two
observations confirm that a process is alive and speaks the expected protocol:
ss -ltnp shows the process and the socket it listens on, and
curl -i shows the response returned. They say nothing about the business
function: the home page can display normally while search, payment or form
submission fails silently behind it. The following sections show this on a
real service.
Two mistakes keep recurring because of this confusion:
- an HTML page that displays is not the whole application: a static home page, or a nicely styled custom error page, can answer while the service's real functions are down;
- a container in the
runningstate is not proof of availability: Docker or any other container engine reports the state of the process it watches, not that of the business function delivered by that process. A process stuck in a wait loop, or one that answers errors on every call, staysrunning.
Checking a production-ready service therefore means testing the business function itself (a search that returns a known result, a test payment that goes through), not just noting that a socket answers. That gap between "the process is running" and "the service delivers what is promised" is what this lesson's service sheet has to record.
How do you observe a running service?
Four commands are enough to describe a running service: ss -ltnp says who
listens, ps says under which account and since when, curl -i says what is
answered, curl -w says the code and the time. Each one queries a different
layer, and the diagram shows which: you start from the client and go down
towards the process, never assuming what you have not observed.
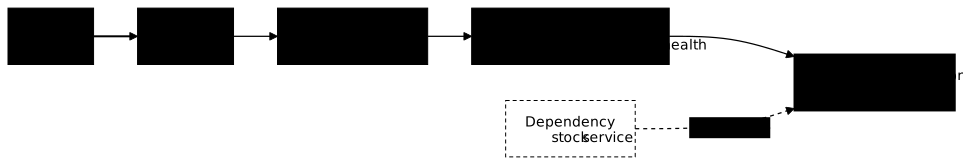
The readings that follow come from a small catalogue service started on my
workstation on 2026-10-25, with curl 8.18.0 and Python 3.12.13.
They are the values of one measurement, not requirements: port 18311, the PID,
the bob account and the durations will be different on your machine, only
the way of reading them matters. This is the same application as the one in
the lab below, without its stock dependency, deliberately missing. First
question, who listens on port 18311? The -l option keeps only listening
sockets, -t TCP, -n numbers rather than names, -p the owning process:
ss -ltnp "sport = :18311"State Recv-Q Send-Q Local Address:Port Peer Address:PortProcessLISTEN 0 5 127.0.0.1:18311 0.0.0.0:* users:(("python3",pid=2786496,fd=4))Three pieces of information can be read here. The address 127.0.0.1 means
the service listens only on the loopback interface: it can be reached only
from the machine itself. A colleague on the network cannot get to it,
which changes everything for publication. (A container has its own
127.0.0.1, distinct from the machine's: a service that listens on loopback
inside a container can be reached only from that container.) The name
python3 and the PID 2786496 identify the process. The Peer column
(0.0.0.0:*) is normal for a listener: no client is connected yet. If ss
returns nothing, nobody listens on that port, and the next question makes no
sense.
Second question, under which account and since when is this process
running? You ask ps, with the PID that ss has just supplied:
ps -o pid,user,etime,args -p 2786496 PID USER ELAPSED COMMAND2786496 bob 00:03 python3 app.pyThe USER column gives the owning account, here bob, my workstation
account. That is already a finding: a production service runs under a
dedicated service account, not under a person's account. The ELAPSED
column gives the age of the process (three seconds, it has just started): a
service supposed to have been running for days whose age shows a few seconds
has restarted, perhaps in a loop. COMMAND gives the launch line, useful to
find the configuration file or the unit that starts it.
How do you check that the service answers, and to what?
curl -i displays the full response, curl -w keeps only the code and the
duration, and you must query several paths: a single path that answers proves
only that path. Here is the home page, with its headers:
curl -sS -i http://127.0.0.1:18311/HTTP/1.0 200 OKServer: BaseHTTP/0.6 Python/3.12.13Date: Sun, 25 Oct 2026 21:09:31 GMTContent-Type: text/htmlContent-Length: 23
<h1>Catalogue-demo</h1>The first line carries code 200, the Content-Type announces HTML and
the body is the application's title: the home page works. The /health
path also answers {"status": "ok"} with a 200. What remains is the function
users expect, the list of books. To compare several paths without flooding the
screen, -w prints one line per call, -o /dev/null discards the body, -s
hides the progress bar:
for chemin in / /health /api/livres; do curl -s -o /dev/null -w "%{http_code} %{time_total}s $chemin\n" \ "http://127.0.0.1:18311$chemin"done200 0.000447s /200 0.000316s /health503 0.000561s /api/livresThis is the heart of the lesson: two paths answer 200, the third 503. The
process runs, the socket listens, the home page displays, the health check is
green, and yet the business function is down. The body of the 503 response
({"error": "stock indisponible"}) points to a dependency, that is,
another component the service needs in order to answer (a database, a stock
service). It is a lead to check, not proof: finding that dependency, its
account and its port is exactly the lab's job. The duration is read in the
second column: here under a millisecond, because the client and the server are
on the same machine. On a real network, this is the value that the
publication contract bounds ("under one second").
What does the client see when the service is stopped?
A stopped service does not answer at all: curl has no HTTP code to display
and -w '%{http_code}' returns 000, which is not a response code but the
admission that no response arrived. You stop the process, then ask the same
two questions:
ss -ltnp "sport = :18311"curl -sS -o /dev/null -w "%{http_code} %{time_total}s\n" http://127.0.0.1:18311/echo "curl a rendu le code de sortie $?"State Recv-Q Send-Q Local Address:Port Peer Address:PortProcesscurl: (7) Failed to connect to 127.0.0.1 port 18311 after 0 ms: Could not connect to server000 0.000116scurl a rendu le code de sortie 7ss now returns only its header: no socket listens any more. curl
displays error 7 ("Failed to connect"), the HTTP code is 000 and its exit
code is 7. Remember the difference from the 503 of the previous section: a
503 comes from a living process that says "I cannot", a 000 means
nobody answered. The two are handled differently: in the first case you
look for the dependency, in the second you look for why the process is no
longer running or no longer listening.
What does a filled-in service sheet look like?
The service sheet records what you have just observed, one line per fact, and each line is verified by a command. Here is the one for the service examined above, in YAML format:
service: catalogueurl: http://127.0.0.1:18311/utilisateur: bobprocessus: python3 app.py (PID 2786496)ecoute: 127.0.0.1:18311dependances: à établirrecette: - "GET / rend 200" - "GET /health rend 200" - "GET /api/livres rend 200 en moins d'une seconde"exploitant: à désignerLet us read it line by line. service and url name what the user knows.
utilisateur, processus and ecoute come from the first two commands (ps
and ss): they are observed facts, not intentions. Here, utilisateur
means the system account that runs the process (the USER column of ps),
not the end users of the contract. The line utilisateur: bob is honest but
reveals a flaw to fix before publication. dependances: à établir admits an
unknown instead of guessing it: better an "à établir" than a plausible and
wrong value. Finally recette lists observable criteria, that is,
sentences a command can confirm or refute. With the readings above, the first
two are met and the third is not: the sheet therefore says by itself that
this service is not ready, which a simple "it runs" would never have revealed.
Note what the sheet does not contain: no public address, no DNS name, no reverse proxy. These elements arrive with publication and feed the contract described above; the sheet describes the service before you touch it. A complete sheet adds the startup, the configuration, the secrets and the state seen above; this one stays minimal to show the gesture.
Practice
The lab gives you a small catalogue application whose page answers but whose business function fails, on a machine where nobody can tell you which process answers, under which account, or what it depends on. You write the service sheet with the gestures of this lesson, you restore the function, then you observe the effect of a restart. The automated tests compare each of your claims with the running system.
Key points
- A client sends a request, a server returns a response that carries a resource in a given representation.
- Process, socket, application, service, static site and API name six distinct things; only the service makes a promise to a user.
- A production-ready service differs from a development server by its reproducible startup, its externalised configuration, its isolated secrets and its controlled state across restarts.
- A publication contract fixes names, URLs, access, availability, latency and operator, before any question of tooling.
ss -ltnpsays who listens (and on which address),ps -o pid,user,etime,argssays under which account and since when,curl -w '%{http_code}'says what is answered; a503comes from a living process that cannot hold its function, a000code means that no response arrived.- A service sheet records observed facts, admits its unknowns
(
à établir) and lists acceptance criteria that a command can verify. - A 200 code or a
runningcontainer prove that a process answers, never that the business function works: you must test that function itself.
Knowledge check
Knowledge check
Check what you have learned with this interactive quiz
How it works
- The timer starts when you click Start
- Multiple choice, true/false and short answer questions
- You can move between questions
- Detailed results are shown at the end
Starts the quiz and the timer
Review
(0/0)Score by domain
A domain groups several guides and gets several questions, so its score is more reliable than a per-topic score, which often rests on a single question.
Summary
Strengths
No topic passed at 80% on at least two questions yet.
Weak areas
No topic below the pass mark.
Recommended next
Hints before you try again?
Continue the course: Read HTTP before configuring a proxy
A new full quiz with random questions
Work again only on the questions you missed