A load balancer sends each request to one of several backends, and it is its health probe, not the number of instances, that decides whether the loss of one of them goes unnoticed. This lesson is for someone who can publish a service behind a reverse proxy and wants to understand what "two instances" really promises. It lays down the concepts common to all tools: what a balancing algorithm changes, what a probe proves, how to compute then measure the removal of a sick backend, and why the load balancer remains a point of failure. The lab has you fix a load balancer that gets each of these points wrong.
What you will learn
The lesson follows the thread of a failure: balance, probe, compute, measure, then look for what remains fragile.
- Explain what a balancing algorithm and weights change, and what they do not guarantee.
- Distinguish a live process, a ready backend and a usable service.
- Contrast the active probe with passive detection, with the limits of each.
- Compute the removal delay and the restoration delay from the interval and the thresholds.
- Measure a removal by the traffic received by the faulty backend, not by the absence of errors.
- Identify the single point of failure of a two-backend topology.
Prerequisites
The lesson assumes you can read an HTTP exchange and place a proxy on the path of a request.
- The path of a request from the client to the backend: Publish a web service.
- The methods and the status codes, in particular
200and503: Read HTTP before configuring a proxy. - What a replay hides from the client: Master timeouts, retries and caching without altering responses.
- No installation: the lab provides the machine, the two backends and the load balancer.
What does this lesson cover, and what does it leave to the tool pages?
This lesson lays down the concepts of balancing and health independently of the tool; the syntax of each proxy lives in its own page. A backend is the instance of the application that actually produces the response. A load balancer is the component placed in front of them, which receives the clients and chooses, for each request, the backend that will handle it. A backend "in rotation" is a backend to which the load balancer sends traffic.
The tool pages take these concepts up with their directives. For HAProxy, Choose the balancing and measure the probes gives balance, check, inter, fall, rise and draining a server. For Nginx, Nginx upstream: balance the load and remove failures gives upstream, max_fails and fail_timeout. The loss of an entry node, that is, of the machine that carries the load balancer itself, is another subject, covered in Test the availability of the HAProxy entry point. Here, the lab uses a teaching load balancer whose policy fits in a YAML file: the vocabulary is neutral so the reasoning transposes.
What does a balancing algorithm really change?
A balancing algorithm only decides which backend receives the next request among those the load balancer considers healthy; it says nothing about their state of health. The simplest is round robin: each backend receives a request in turn. Least connections sends the request to the backend that is handling the fewest at the moment of choice, which suits very uneven processing times. Random draws a backend at random. Hashing ties a client to a backend, which gives affinity: the same client lands on the same instance.
Weights declare the relative capacity of the backends. A backend of weight 3 facing a backend of weight 1 receives three requests out of four when both are healthy. Affinity is useful when the instance keeps a session's state in local memory, but it has a price: if that backend is removed, its clients go elsewhere and lose what that memory contained.
One point surprises beginners: a perfect alternation is almost never measured. As soon as several clients send requests at the same time, the weights differ or the algorithm draws at random, the observed sequence no longer looks like "a, b, a, b". A sample of eight requests on a random draw across two backends misses one of the two about once in a hundred and twenty-eight times (twice the probability of eight identical draws, so 2 in 256: a computation, not a measurement). The right question is therefore not "is the order regular?" but "do both backends receive traffic?". That is exactly what the lab checks, without imposing an exact alternation.
The lab's load balancer starts with a policy that disables balancing: as long as both backends answer, it sends everything to the first in the list and never touches the second. Only a traffic sample reveals it. An instance that never serves is neither extra capacity nor an insurance: it is an unknown backend, of which nobody knows whether it works.
Is a live backend therefore usable?
No: a backend can be live, that is, have a running process and an open port, while being unable to serve a useful request. Three levels must be distinguished. The live process (liveness) answers the question "is it running?". The ready backend (readiness) answers "can it serve now?", which assumes its dependencies, a database for example, answer too. The usable service is what the client experiences: a real request that succeeds.
An application failure illustrates the gap. The process runs, the port accepts connections, but the application has lost access to its database. A check that merely opens a TCP connection sees a healthy backend, while every useful request fails. Kubernetes opposes the same notions: see Kubernetes probes: liveness, readiness, startup without false positives (in French).
In the lab, each backend exposes a health route, /sante. Placing a flag file on a backend simulates the application failure: this route then answers 503 instead of 200. Note an instructive detail of the test bench: the backend marked sick keeps answering normally on its service route. The simulated failure is visible only from the health route, which is the most insidious case, the one a good probe must cover.
What does a probe prove, and what does it not prove?
A probe proves that a specific route answered as expected at a given moment; it never proves that clients' requests will succeed. A probe is a request that the load balancer emits by itself, at regular intervals, to a dedicated route of each backend, to decide whether to keep it in rotation. It is called an active probe, as opposed to passive detection, where the load balancer emits nothing and deduces a backend's health from the real requests of the clients it has sent to it.
The table below compares the two models. Read it column by column: each has a blind spot that the other fills.
| Question | Active probe | Passive detection |
|---|---|---|
| Who learns of the failure? | The load balancer, through its own requests | The load balancer, through the result of client requests |
| With no traffic at all? | The failure is seen | Nothing is seen: no request, no information |
| Cost | Extra requests, permanently | Failures suffered by real users |
| Blind spot | Tests only the health route | Detects only what real traffic exercises |
Neither is better in the absolute, and the tool pages show it: HAProxy probes actively, whereas open source Nginx only does passive detection. An active probe has two limits to know. The first: its health route can lie by omission, answering 200 while the database is down, because nobody put the test in it. The second is the opposite: a health route that queries a dependency shared by all the backends removes them all at once the day that dependency slows down, and the whole service goes down for a failure each backend could have absorbed. A good health route checks what the backend needs to serve, no more.
How do you measure a backend's removal without trusting errors?
You measure a backend's removal by the traffic it still receives, never by the absence of errors on the client side. Two things must be separated: the failures counted by the load balancer, which feed its decision to remove a backend, and the errors seen by the client. A replay (sending the failed request to another backend) can hide the failure from the client while the load balancer did count it. Detection learns from the requests sent to the backend, not from the errors that reach the client.
The criterion "the client no longer sees an error" is therefore misleading. Imagine a failed backend that the load balancer never removed: if each request that lands on it is replayed on the other, the client sees no error, and the measurement is green without detection. A criterion that also succeeds when the tested function is absent discriminates nothing. The honest criterion concerns what differs between a tuned detection and an absent one: after a delay, the faulty backend no longer receives traffic, and receives some again once restored.
The method comes down to three gestures. Identify each backend in its response, for example by a field "backend a" or "backend b". Send a small finite sample of requests through the load balancer and note which identities answer. Wait for the planned window and start again, until the faulty backend's identity disappears from the sample. The lab's test looks only at these identities: it replays a small sample every second, and requires that the sick backend has disappeared and that the healthy one is still there.
This second condition counts as much as the first. A load balancer that returned 503 to everyone would also "remove" the faulty backend from the sample, but would serve nobody any more. An honest removal is therefore read on both sides: the faulty one disappears, the healthy one keeps receiving.
How do you tune a probe's interval and thresholds?
A backend's removal delay is roughly the probe interval multiplied by the failure threshold, and the restoration delay is the interval multiplied by the success threshold. The interval is the time between two probes. The failure threshold is the number of consecutive failures that removes a backend from rotation; the success threshold is the number of consecutive successes that puts it back. The word consecutive is decisive: a single success in the middle resets the failure counter to zero.
The diagram below shows a backend's two states and the two counters that link them. Follow the thick arrow at the top: N failures in a row remove the backend. Follow the one at the bottom: M successes in a row bring it back. The dotted arrows recall the reset.
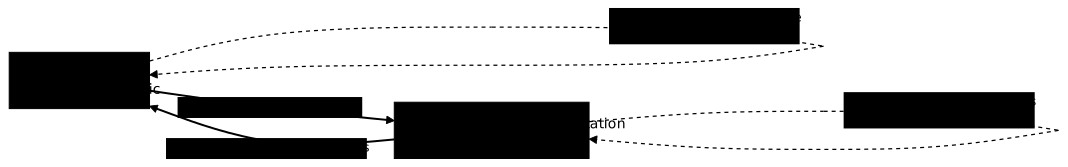
Do the computation on the lab's starting configuration, which probes every 20 seconds and requires 20 failures: a sick backend stays in rotation for something like 400 seconds, nearly seven minutes, and since the return threshold is the same, a restored backend waits as long. If the load balancer alternates, one request in two lands during that time on a backend that serves nothing. The lab's test grants 12 seconds for the removal, then 12 more for the return, and samples every second: the product of the interval by the threshold must therefore fit well under this window, sampling margin included. The reasoning holds beyond the lab: you choose a delay you can defend, then deduce the interval and the threshold.
Why not set everything to 1 to react as fast as possible? Because every hiccup then becomes a switchover. A restart, a pause of a few seconds or a network micro-outage fails a single probe; with a threshold of 1, the backend leaves rotation, all traffic shifts onto the other, and this shift can bring the second one down in turn. The failure threshold therefore protects against instability. The return threshold protects the same way in the other direction: with a success threshold of 1, a single capricious probe brings back into rotation a backend that is not healed. A threshold higher than 1 is a trade-off: more patience against fewer oscillations.
A probe finally has its own timeout. A backend that answers after several seconds is counted as failed when the probe gives up before its response, and this failure counts like any other in the threshold. A short interval detects quickly, but multiplies the probes, and a probe that queries the database can load an already fragile service.
What becomes of the service when a backend is removed?
When a backend is removed, the remaining backend carries all the traffic, and the question to ask before the failure is whether it can bear it. Two backends of the same size give, once one is removed, a single server facing the load that was spread over two. If each was already running at 70% of its capacity, the survivor must absorb 140%: it saturates, answers slowly, and the probe, which also queries it, ends up removing it in turn. This is the remaining capacity, and it is computed cold, before the incident.
When no backend is healthy any more, the load balancer has nobody left to send requests to. The lab's one then returns a 503 with a message "aucun backend sain" (the lab's own wording, in French: "no healthy backend"). It is the honest answer: a clear error is better than a hanging connection.
Removing abruptly is not the only way to take a server out. For a planned maintenance, you drain the server: you stop assigning it new requests while letting the ones in progress finish. The lab does not have you practice it; the page Choose the balancing and measure the probes details it for HAProxy.
Do two backends suffice to make the service available?
No: as long as the load balancer is single, two backends do not make the entry point available, because the load balancer is itself a single point of failure. A single point of failure is a component whose loss stops the whole service, whatever the number of copies of the others. Adding backends protects against the loss of a backend; it does not protect against the loss of what precedes them.
The lab demonstrates it honestly. It stops the load balancer, then queries the two backends directly: each still answers. Yet, from a client's point of view, which only has the load balancer's address, nothing answers. The backends are live, ready, healthy, and unreachable by the path the client takes. The sentence "it has two instances" describes a capacity to survive an instance failure, not an availability of the service.
This limit is not fixed by tuning the probe better: it requires duplicating the entry point itself, which Test the availability of the HAProxy entry point covers for HAProxy. Remember here the reflex that reveals it: for each topology, ask "if I remove this component, who still answers the client?", and start again for every component on the path.
Practice
The lab gives you two identical backends behind a provided and opaque load balancer, with probes and thresholds configurable in a policy file reread at each probe, without restart. The delivered configuration carries three mistakes at once. You fix them with the help of the provided prober, which sends real HTTP requests and notes the identities that answer. The validation measures four things: the two healthy backends both receive traffic, a backend marked sick leaves rotation within a reasonable window while letting the healthy one serve, it returns to it within a reasonable window once restored, and stopping the load balancer makes both backends unreachable by the client's path while they still answer directly.
Key points
- A balancing algorithm chooses a backend among those considered healthy: it does not judge their health, and the alternation observed is never perfect.
- The right balancing criterion is that each healthy backend receives traffic, not that the order is regular.
- A live process is not a ready backend, and a ready backend is not a usable service; the health route must check what the backend needs to serve.
- An active probe queries a dedicated route and sees a failure without traffic; passive detection learns from clients' real requests and sees nothing without them.
- The removal delay is roughly the interval multiplied by the failure threshold, the return delay the interval multiplied by the success threshold, both counted on consecutive probes.
- Thresholds at 1 turn every hiccup into a switchover; thresholds that are too high let a sick backend serve for minutes.
- A removal is measured by the traffic the faulty backend still receives, never by the absence of errors: a replay hides the errors from the client while the failure is counted.
- A single load balancer remains a point of failure: two backends do not make the entry point available.
Knowledge check
Check that you can reason about the health of a service behind a load balancer, without relying on a specific tool.
Knowledge check
Check what you have learned with this interactive quiz
How it works
- The timer starts when you click Start
- Multiple choice, true/false and short answer questions
- You can move between questions
- Detailed results are shown at the end
Starts the quiz and the timer
Review
(0/0)Score by domain
A domain groups several guides and gets several questions, so its score is more reliable than a per-topic score, which often rests on a single question.
Summary
Strengths
No topic passed at 80% on at least two questions yet.
Weak areas
No topic below the pass mark.
Recommended next
Hints before you try again?
Continue the course: Observe the service delivered and prepare alerts
A new full quiz with random questions
Work again only on the questions you missed