You only protect well what you know about. Inventorying your secrets means drawing up the complete list of passwords, API keys and tokens that exist in your system, knowing where they are and who uses them. It rests on three pillars: a register that records each secret and its details, a regular discovery that hunts down forgotten secrets, and a classification by criticality that says which to protect first. It is not a one-off task: it is a continuous loop, because new secrets keep appearing. This lesson extends the definition of a secret and requires no other technical prerequisite.
What you will learn
Many teams protect a few known secrets while ignoring dozens of others forgotten in files, images or old repositories. This lesson gives you the method to stop being one of them. Concretely, you will be able to:
- Understand why the inventory is the starting point of any protection of secrets.
- Keep a register that records for each secret its type, owner, location, consumers, criticality and rotation date.
- Organise the discovery to find secrets forgotten in code, images and workstations on a regular basis.
- Classify your secrets by criticality and by type, to know which to protect first.
- Connect this approach to the detection of exposed secrets and to the SOCLE threat model for secrets (in French).
Why inventory your secrets?
Security follows a simple rule: you only protect well what you know about. A secret whose existence you ignore is a secret that nobody watches, nobody renews and nobody revokes (cancels) the day it leaks. The inventory is therefore the very first gesture of secrets management: before choosing a vault or a renewal rule, you must know what you hold.
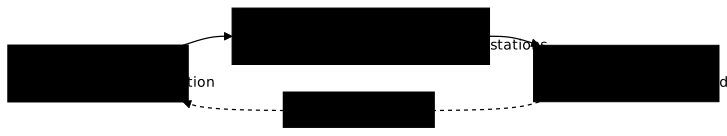
The problem is that secrets proliferate naturally. Every new service, every integration, every deployment creates its API key, its password or its token. Nobody keeps count, and this silent accumulation forms a debt: secrets created "to test", copied into a file on the side, left in an old repository. They are so many keys lying around, often with broad rights, that nobody remembers.
This debt is all the more dangerous because it is invisible. A team can think it handles its ten known secrets cleanly while letting the fifty it forgot leak. The inventory makes this hidden mass visible. It turns a vague "we do not really know" into a clear map, a necessary condition to act.
What does the register record for each secret?
The first pillar is the secrets register: a document, a table or a tool that lists every existing secret with the information useful to manage it. The form hardly matters at first; what counts is to record the same fields for each secret, so as to know at a glance what it is and what depends on it.
Here is the information to record for each secret:
- The type: the nature of the secret (password, API key, token, private key, certificate). The type determines how the secret is protected and replaced.
- The owner: the person or team responsible for this secret. They are the ones to warn if it leaks and the ones who decide to renew it. A secret without an owner is a secret nobody manages.
- The location: where the secret is stored (in a vault, an environment variable, a configuration file). Knowing where it lives lets you find it and secure it.
- The consumers: the applications, services or people that use this secret. This information is crucial: the day you must replace a secret, it tells you exactly what to update so as to break nothing.
- The criticality: the damage its leak would cause, a notion detailed below in the part on classification. It says in which order to act when several secrets are affected.
- The rotation date: the last time the secret was replaced by a new one (rotation means renewing a secret, that is replacing it by a new one at regular intervals). A secret not renewed for years is a risk, because the longer it lives, the more chances it has had to leak.
The value of the register shows on the day of an incident. If an API key leaks, the register immediately tells you who is responsible for it, where it is stored and which services use it. Without it, you start blind, searching in a panic for the systems that will fall over if you revoke the key. The register turns an emergency into a controlled operation.
A register line never contains the value of the secret, only its metadata. The table shows what three lines look like, for a fictional online ordering system:
| Secret | Type | Owner | Location | Consumers | Criticality |
|---|---|---|---|---|---|
db-orders | Password | Platform team | Vault | Orders API, shipping worker | Critical |
payment-api-key | API key | Payments team | Environment variable | Billing service | Critical |
stats-token | Token | Data team | Configuration file | Internal dashboard | Minor |
The second line stands out: a critical key in an environment variable is a flaw that the register makes visible and that will have to be fixed by moving it to a vault.
How do you find forgotten secrets?
A register is only worth something if it is complete. Yet nobody thinks of recording the "temporary" secrets, those pasted in an old file or inherited from a former project. This is the role of the second pillar: secrets discovery, which consists in actively searching your system to hunt down the secrets the register does not know yet.
Discovery targets the places where secrets hide most often. Three of the four come from the leak points presented in the lesson What is a secret in computing? (code, Git history, container images); the fourth, the workstations, is specific to the inventory:
- The code repositories, where a secret lies in clear text in a program file.
- The Git histories, which keep a secret that was removed from the code today.
- The container images, which can embed a secret and distribute it with themselves.
- The workstations: passwords and keys stored in the configuration files of developers' machines.
Discovery is not a manual gesture: specialised tools scan these sources and flag everything that looks like a secret. Each secret found then joins the register, or triggers an action if it should never have been there. For the practical side of this scan, with the tools and the method, see the dedicated page on detecting exposed secrets.
How do you classify secrets by criticality and type?
Once your secrets are listed, they are not all equal. The third pillar is the classification: sorting your secrets by importance to concentrate effort where the risk is highest. You do not protect the password of an internal tool with no data the same way as the key that opens your whole infrastructure.
The first axis is criticality: what damage the leak of this secret would cause. A critical secret opens broad access or touches sensitive data; its leak would be serious. A minor secret gives limited access, with no major consequence. Classifying by criticality lets you say clearly which secrets must be protected first, watched closely and renewed most often.
The second axis is the type of secret. A password, an API key and a certificate are not replaced the same way and do not have the same lifespan. Classifying by type helps organise the rotation, that is the regular replacement of a secret by a new one, by applying to each family the rule that suits it.
This double classification, by criticality and by type, guides all the following decisions. It shows where to place the little time and vigilance a team has: critical secrets go into a solid vault with frequent renewal, while the less sensitive ones follow lighter handling. Without classification, you protect everything the same way, hence badly, for lack of means.
How do you put the inventory into practice?
In practice, the inventory is built in two complementary movements. The first is discovery: run a scan of your repositories, images and workstations to draw up a first list of what really exists. This is the concrete starting point, described in the page detect exposed secrets, which shows how to spot these secrets where they hide.
The second movement is centralisation in a secrets vault, the software defined in the lesson What is a secret in computing?. Once your secrets are listed and classified, putting them in a vault turns your register into a living system, where each secret has a single, watched place. The HashiCorp Vault guide presents a concrete and very widespread vault, in action.
The inventory also feeds the secret lifecycle: knowing what you have means being able to decide when each secret must be renewed and when it must disappear. The register is the memory that makes this management possible over time. The first stage of that lifecycle actually takes up this register with a finer grid of secret classes and an example of a minimal register in YAML: the lesson that contains it comes after this one, when moving from method to tooling.
What pitfalls should you avoid?
The inventory of secrets always fails in the same way, and knowing these pitfalls in advance helps you avoid repeating them.
The most frequent pitfall is the inventory done once and never updated. A team spends a week listing all its secrets, produces a nice table, then forgets it. Six months later, that table no longer describes reality: new secrets have appeared, others have disappeared. A frozen inventory gives false security, believing you are in control while the map is out of date. That is why the inventory is a continuous loop and not a one-off project: register, discovery and classification run permanently.
The second pitfall is that of ghost secrets: secrets that exist and still work, but that the register ignores. They are the most dangerous, because nobody watches or renews them. They often outlive the departure of the person who created them, with no owner to care. Only a regular discovery can catch them before they become an entry point.
The third pitfall is classifying too finely from the start. Wanting ten levels of criticality on day one paralyses the approach. It is better to have two or three simple categories applied to all secrets than a clever classification nobody keeps up to date. Simplicity is what keeps the inventory alive over time.
Key points
-
You only protect well what you know about: the inventory is the mandatory starting point of any secrets management.
-
Secrets proliferate: each service creates its own, forming an invisible debt that must be made visible.
-
The register records for each secret its type, owner, location, consumers, criticality and rotation date.
-
Regular discovery hunts down secrets forgotten in code, images, workstations and histories.
-
Classification by criticality and by type says which to protect and renew first.
-
It is a continuous loop: a frozen inventory gives false security, and ghost secrets are the most dangerous.
-
The proof expected by the SOCLE reference framework: an up-to-date inventory with type, owner, location, consumers and criticality (SOCLE-SEC-GEN-1), kept as a register (SOCLE-SEC-INV-1), completed by a regular discovery (SOCLE-SEC-INV-2) and a classification of secrets (SOCLE-SEC-INV-3). The SOCLE threat model for secrets (in French) links these requirements to the attacks they block.
Knowledge check
Check that the essentials of this lesson are in place. The questions only cover what has just been explained here.
Knowledge check
Check what you have learned with this interactive quiz
How it works
- The timer starts when you click Start
- Multiple choice, true/false and short answer questions
- You can move between questions
- Detailed results are shown at the end
Starts the quiz and the timer
Review
(0/0)Score by domain
A domain groups several guides and gets several questions, so its score is more reliable than a per-topic score, which often rests on a single question.
Summary
Strengths
No topic passed at 80% on at least two questions yet.
Weak areas
No topic below the pass mark.
Recommended next
Hints before you try again?
Continue the course: Secret lifecycle: the 8 key stages
A new full quiz with random questions
Work again only on the questions you missed