
You want to build an assistant that answers questions about your internal documentation, runs commands on your servers and generates reports. Where do you start? Which building blocks do you use? This guide gives you, in 15 minutes, a structured overview of the generative AI ecosystem.
What you will learn
- LLM: what a language model is and how it generates text
- RAG: how to augment an LLM with your own data
- Tool calling: how an LLM calls functions
- Agents: how an LLM can act on the real world through tools
- MCP: the standard that connects agents and tools
- Where the tools fit: LiteLLM, Ollama and LangGraph in the architecture
How to choose (in 30 seconds)
Before going into the detail of each building block, this table maps a need directly to the matching technique. Read it as a switchboard: first identify what you want to do, and the right-hand column sends you to the section that explains it. The four rows are not mutually exclusive: a complete assistant often combines RAG, tool calling and an agent loop.
| You want to... | Use... |
|---|---|
| Answer questions about your internal docs | RAG (search + context injection) |
| Trigger an external action (API, DB, shell) | Tool calling |
| Chain several steps / loop until the result is reached | Agent (LangGraph, CrewAI...) |
| Reuse your tools in Claude Desktop, VS Code, etc. | MCP (interoperability standard) |
LLM: text generation
An LLM (Large Language Model) is a program that predicts the next token in a sequence. A token is not necessarily a word: it is a piece of text (a word, part of a word, punctuation). From the text already present, the model computes for each possible token the probability of being the next one, picks one, appends it to the sequence, then starts again. By repeating this prediction thousands of times, it produces whole paragraphs.
In practice, an LLM can:
- Generate text: articles, emails, code, scripts
- Answer questions: by synthesizing what it has "learned"
- Summarize documents: by extracting the essentials
- Translate: by transposing the patterns of one language into another
- Rephrase: by changing the style or the level of complexity
How it works in practice
The LLM was trained on billions of texts (books, websites, source code, conversations). During this training, it "learned" the statistical patterns of language: which words follow which others, and in which context.
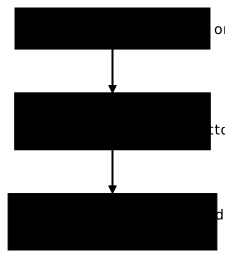
The LLM picks the next token according to probabilities, then repeats the process until it has generated a complete answer. This token-by-token generation explains why people talk about "cost per token" and "context window".
What an LLM knows and does not know
| The LLM knows | The LLM does not know |
|---|---|
| The syntax of the language | Events after its training date |
| Common patterns | The content of your internal documents |
| How to generate valid code | The truth (it sometimes "hallucinates") |
| How to follow instructions | How to act on the real world |
The main LLM families (October 30, 2026)
| Family | Examples | Particularity |
|---|---|---|
| GPT (OpenAI) | GPT-6 Astra, GPT-6.1 Sol, GPT-6.1 Terra, GPT-6 Luna | Cloud API, range from most capable to most efficient, reasoning |
| Claude (Anthropic) | Claude Fable 5.1, Opus 5.5, Sonnet 5.5, Haiku 5.5 | 1M-token context, API and partner clouds |
| Meta (Llama, Muse) | Muse Spark Open | Open-weights; Meta's developer page no longer presents Llama among its current models |
| Mistral | Mistral Large 4, Medium 3.5, Small 4, Codestral 25.08 | European vendor, several open-weights models under varied licenses |
| Gemini (Google) | gemini-4-argon, gemini-3.8-flash | Text, image, audio and real-time range |
| Qwen (Alibaba) | Qwen3.8 (27B, 2.4T-A95B) | Weights published on Hugging Face and ModelScope, check the license |
→ Go deeper: Anatomy of an LLM (in French)
RAG: augmenting the LLM with your data
You have an LLM, but it does not know your internal documents. How do you get it to answer "What is our leave policy?" or "How do we deploy on our infrastructure?" This is where RAG (Retrieval-Augmented Generation) comes in.
The principle in 4 steps
RAG comes down to one idea: instead of asking the LLM what it "knows", you give it the right passages from your documents at question time, and ask it to answer from that text. The four steps below are read in order, but two of them happen at different moments: indexing is done once, in advance, whereas search, injection and generation chain together on every question asked.
- Index: turn your documents into numerical vectors (detailed below)
- Search: when a question arrives, find the relevant passages
- Inject: add those passages to the LLM's prompt
- Generate: the LLM answers based on that context

Why RAG rather than fine-tuning?
| Approach | Advantages | Drawbacks |
|---|---|---|
| RAG | No retraining, up-to-date data, traceability (citations) | Depends on the quality of the search |
| Fine-tuning | Customized behavior, no search latency | Expensive, frozen data, risk of forgetting |
The steps of a RAG pipeline (explained)
Here is the detail of the six operations that turn a pile of documents into sourced answers. The first four (extraction, chunking, embeddings, indexing) make up the preparation phase, run only once. The last two (retrieval, generation) form the execution phase, replayed on every question. Note the chunking step: the size of the pieces you choose there alone determines the relevance of everything that follows.
-
Extraction: retrieve the raw content of your sources (HTML, PDF, Markdown). This is the "web scraping" or "parsing" of your documents.
-
Chunking: split the content into pieces of 500-1000 tokens. Why? Because the LLM has a limited context window, and because a short passage is more relevant than a whole document.
-
Embeddings: convert each chunk into a numerical vector (a list of numbers). Each vector places the chunk in a space of several hundred dimensions where two texts with a close meaning get close coordinates, which makes their similarity measurable with a simple distance calculation.
-
Indexing: store these vectors in a vector database (ChromaDB, FAISS). It is a database optimized for finding "the closest vector".
-
Retrieval: when a question arrives, convert it into a vector too, then look for the closest chunks. This is "semantic search".
-
Generation: inject the chunks found into the LLM's prompt. It answers based on that context, not on its memory.
What makes the difference in production
A "demo" RAG works quickly. A production-ready RAG needs 3 extra elements:
-
Metadata and filters: each chunk carries information (source, date, product, ACL). Without it, you cannot filter by team, restrict by permissions, or date the answers.
-
Hybrid retrieval + reranking: combine dense search (embeddings) and lexical search (BM25), then re-rank the results with a reranking model. A significant gain in relevance.
-
Citations / traceability: return to the user the excerpts used, with their links or IDs. Without this, it is impossible to verify or audit.
→ Go deeper: Introduction to RAG (in French)
Agent: an LLM that acts
So far, the LLM only talks. But if you want it to act, to book a flight, deploy a service, send an email, it needs tools and a decision loop. This is what is called an agent.
In practice, an agent can:
- Call APIs: weather, Slack, GitHub, your backend
- Run code: Python, shell, SQL
- Read/write files: logs, configs, reports
- Query databases: PostgreSQL, MongoDB, Elasticsearch
- Browse the web: scrape, fill in forms
The agent loop (explained)
The agent works in a loop until the task is finished:
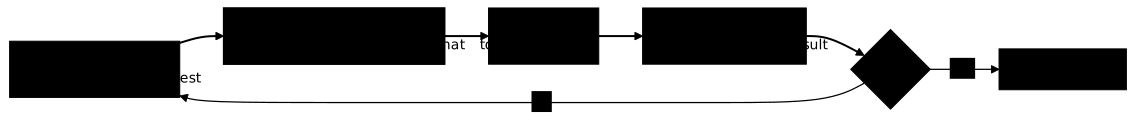
Each step has a precise role:
- PERCEIVE: the agent receives the request ("Deploy version 2.1 to staging")
- THINK: the LLM analyzes the situation and decides what to do ("First I need to check whether staging is available")
- ACT: it calls a tool (
check_status("staging")) - OBSERVE: it reads the result ("staging: OK, ready")
- Start again?: if the task is not finished, back to THINK ("Now I can deploy")
Agent vs chatbot
| Simple chatbot | Agent |
|---|---|
| Answers a question | Accomplishes a task |
| A single LLM interaction | Several iterations |
| No external action | Calls tools |
| Deterministic | Autonomous (and risky) |
Common agent patterns
| Pattern | Description | Use case |
|---|---|---|
| ReAct | Alternating reasoning and action | Complex multi-step tasks |
| Plan-Execute | Plan first, execute afterwards | Tasks with dependencies |
| Reflection | Self-critique and correction | Improving quality |
| Router | Route to the right sub-agent | Specialization by domain |
→ Go deeper: Agentic patterns: ReAct, Plan-and-Execute, Reflexion (in French)
Tool calling: the LLM calls functions
You may wonder: "How does the LLM know how to call an API?" The answer: it does not really do it. The LLM generates structured text (JSON) that describes which function to call and with which parameters. It is your code that actually performs the action.
This is tool calling (or function calling): a convention where the LLM "asks" for a function to be called, and your code executes it.
How it works in practice
- You define tools with their schemas (name, description, parameters)
- The user asks a question
- The LLM decides which tool to call and with which parameters
- Your code runs the tool and returns the result
- The LLM integrates the result into its answer
# Definition of a tooltools = [    {        "type": "function",        "function": {            "name": "get_weather",            "description": "Get the weather of a city",            "parameters": {                "type": "object",                "properties": {                    "city": {"type": "string", "description": "Name of the city"},                    "unit": {"type": "string", "enum": ["celsius", "fahrenheit"]}                },                "required": ["city"]            }        }    }]
# The LLM generates this (not the result, just the call):# {"name": "get_weather", "arguments": {"city": "Paris", "unit": "celsius"}}
# Your code runs get_weather("Paris", "celsius") → "18°C, cloudy"# The LLM answers: "It is 18°C in Paris, with a cloudy sky."
Do not confuse the two building blocks:
- RAG: inject static context (documents)
- Tool calling: trigger dynamic actions (API, code)
The two are complementary: an agent can use RAG to look up information, then tool calling to act.
→ Go deeper: Function calling: connecting an LLM to real tools (in French)
MCP: the standard for connecting tools
You built a "get_weather" tool for your LangGraph agent. Great! But now you want to use it in Claude Desktop, VS Code Copilot and your Chainlit chatbot. Are you going to rewrite the integration 3 times? This is exactly the problem that MCP (Model Context Protocol) solves.
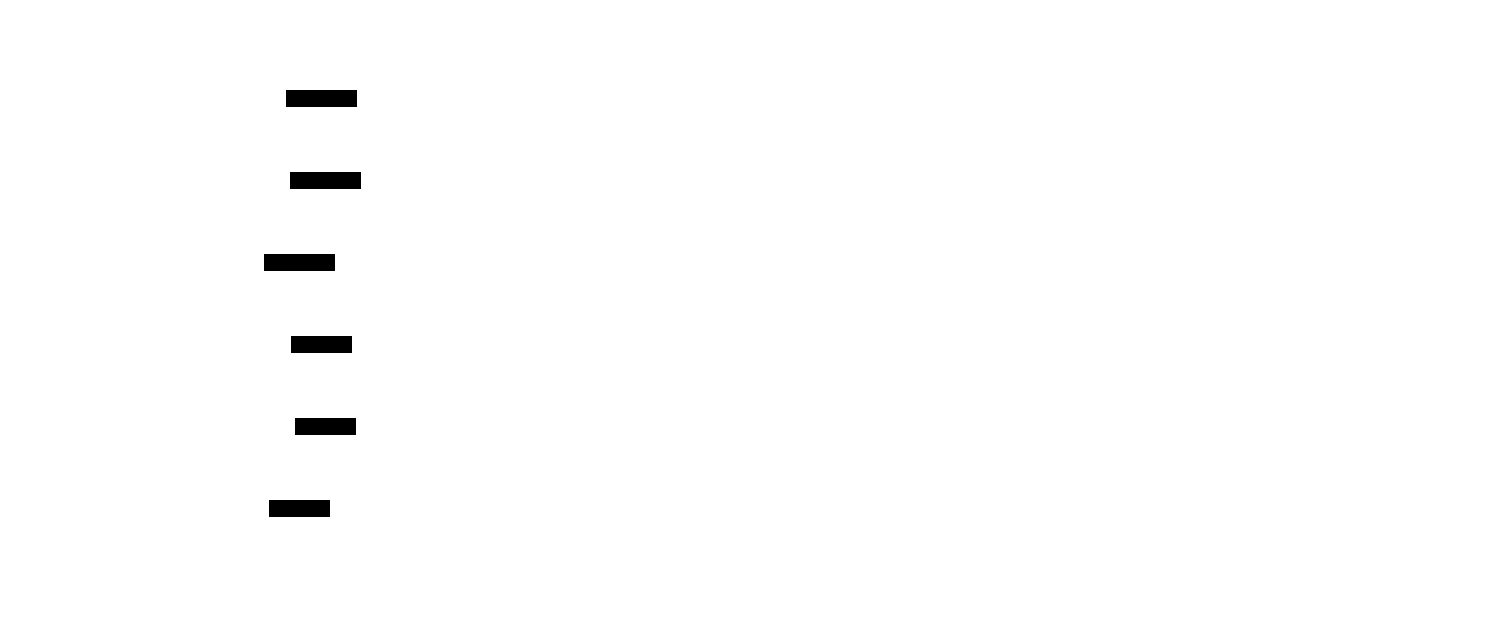
The N×M problem (before MCP)
Without a common standard, each application (Claude Desktop, VS Code, your chatbot) must be connected to each tool by a custom integration. With N applications and M tools, that makes N×M integrations to write and maintain. The diagram below shows what MCP changes: by stepping in as a common protocol, it brings this cost down to N+M, with each application and each tool talking to a single standard counterpart.
MCP architecture
MCP splits the roles into three components that you need to tell apart to read any documentation of the protocol. The point often misunderstood is the place of the client: it is not the user, but a library housed in the host application, whose only job is to maintain the connection to the servers that expose the tools.
| Component | Role | Example |
|---|---|---|
| Host | The user-facing application | Claude Desktop, VS Code, Chainlit |
| Client | Maintains the connection to servers | MCP library |
| Server | Exposes resources, tools, prompts | Your MCP server |
The 3 MCP primitives
| Primitive | Description | Example |
|---|---|---|
| Resources | Contextual data (read-only) | Files, DB entries |
| Tools | Functions callable by the LLM | check_status(), deploy() |
| Prompts | Reusable templates | "Summarize this incident" |
MCP was announced on November 25, 2024 by Anthropic. It is a protocol (not a framework) that relies on JSON Schema to describe tools.
The ecosystem evolves quickly, so check the official specification for the latest changes.
→ Go deeper: Understanding the Model Context Protocol (MCP) (in French)
A concrete example: a DevOps assistant
To understand how everything fits together, let us take a complete DevOps assistant:
The need
You want an assistant that can:
- Answer questions about your internal documentation (procedures, runbooks)
- Check the state of your services
- Retrieve logs
- Create incident tickets
The solution, building block by building block
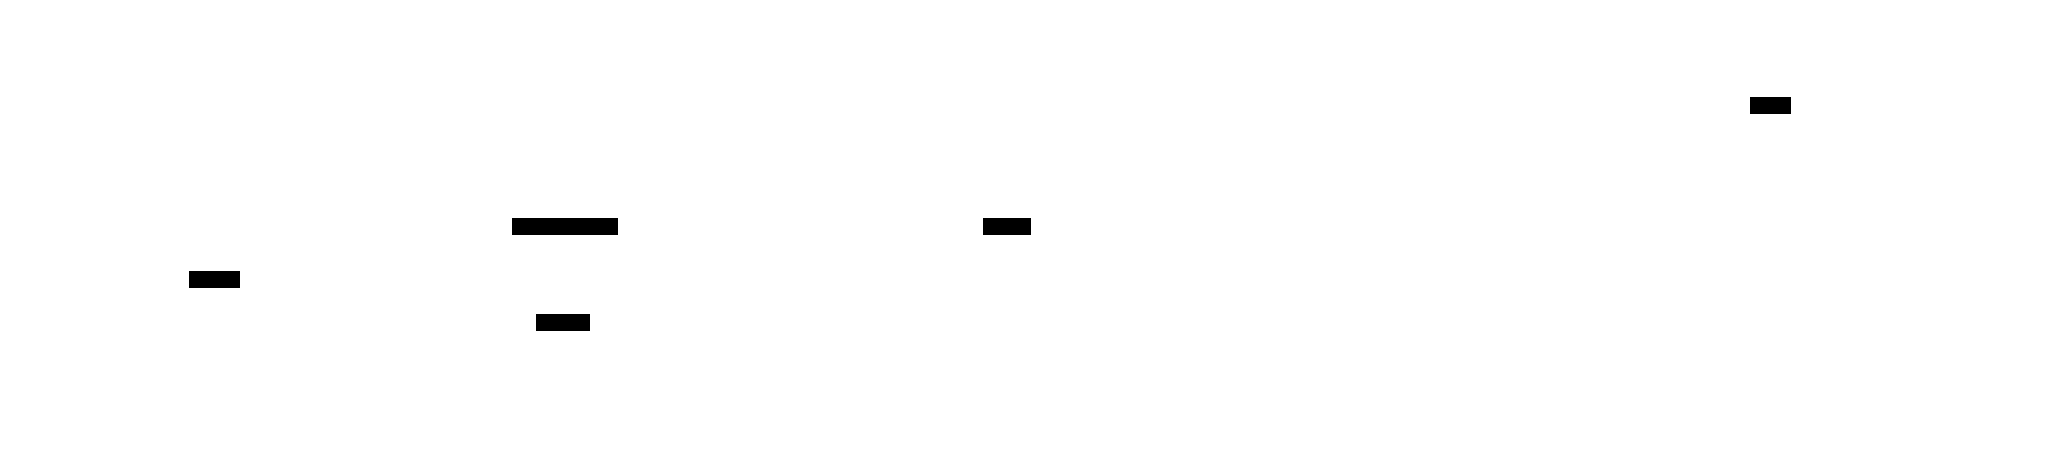
This table is the summary of the whole guide: each need of the assistant translates into a building block seen earlier. Read it from top to bottom like a construction plan. Note that tool calling comes back three times: as soon as the assistant has to act on a real system (check a service, read logs, create a ticket), it is always tool calling at work, with the agent only orchestrating these calls. On the inference side, LiteLLM is an open source library that calls more than a hundred LLMs behind a single interface: switching providers, or moving to a local model served by Ollama, does not require rewriting the code.
| Need | AI building block | Implementation |
|---|---|---|
| Answer from the internal docs | RAG | ChromaDB with your runbooks indexed |
| Check the state of services | Tool calling | check_status(service) tool |
| Retrieve logs | Tool calling | get_logs(service, lines) tool |
| Create a ticket | Tool calling | create_ticket(title, body) tool |
| Orchestrate all this | Agent | LangGraph with a decision loop |
| Standardize the tools | MCP | "devops-tools" MCP server |
| User interface | - | Chainlit or Slack bot |
| Inference | LLM | an OpenAI model through LiteLLM (with Claude fallback), or an open-weights model served by Ollama behind the same LiteLLM |
The resulting architecture
Common mistakes
To finish, here are four common confusions and the right approach for each:
| Mistake | Why it is wrong | Right approach |
|---|---|---|
| "RAG = fine-tuning" | RAG injects context on the fly; fine-tuning changes the model's weights | Use RAG for changing data, fine-tuning for a permanent customized behavior |
| "An agent = a chatbot" | A chatbot answers; an agent acts (loop, tools, autonomy) | Chatbot for simple Q&A, agent for multi-step tasks |
| "MCP secures my tools" | MCP is an interoperability protocol, not a security one | Add sandbox, allowlist and audit on top of MCP |
| "The LLM calls the API" | The LLM generates JSON; your code runs the call | Always validate the JSON before execution |
Key takeaways
-
LLM = generation: predicts the next token. The basis of everything. But only knows what it learned.
-
RAG = context: augments the LLM with your data. Search + injection into the prompt.
-
Tool calling = interface: the LLM generates JSON, your code executes. Always validate.
-
Agent = action: LLM + loop + tools. Autonomous but risky. Guardrails are mandatory.
-
MCP = standard: connects apps and tools. Avoids N×M. Resources, Tools, Prompts.